How to build a 4-agent team, that ships a feature while you sleep (Exact Setup Inside)
Four AI agents can ship a feature while you sleep. Most people never wire them up.They fire a reviewer here, a test generator there, by hand...
📋 文章摘要
核心主题:利用 Claude Code 的 Subagent 机制构建一条 4 阶段 AI 流水线,睡前触发一次 /ship 命令,醒来即可拿到功能实现 + 代码审查结论。
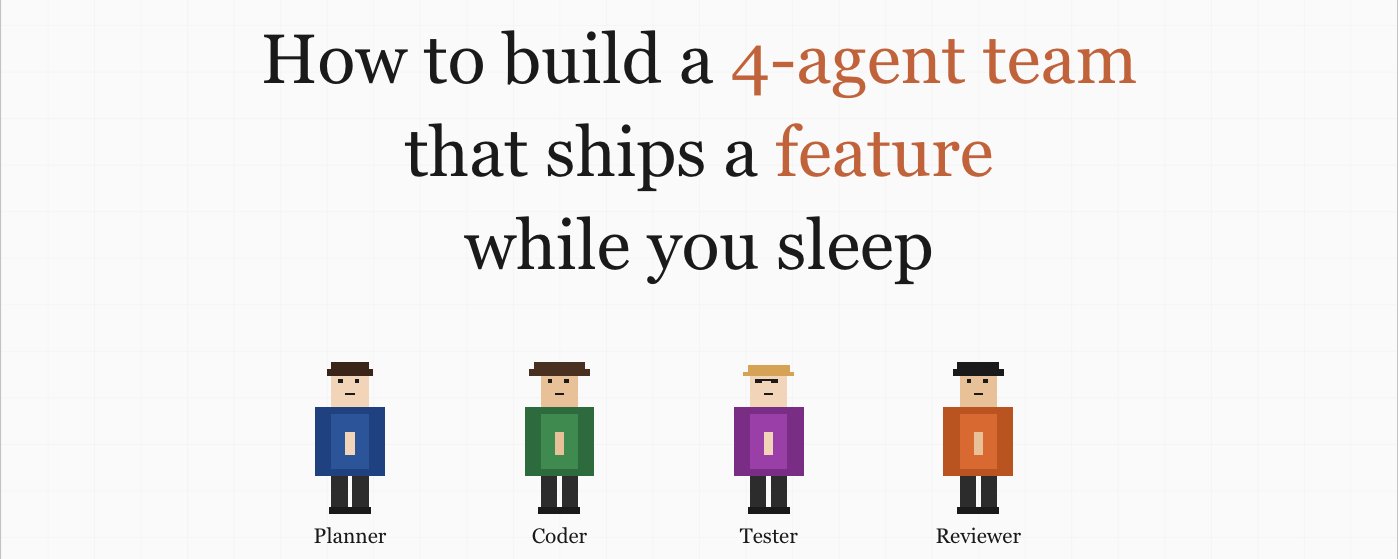
流水线架构:Planner → Coder → Tester → Reviewer,各阶段通过 .pipeline/ 目录下的交接文件(handoff file)串联:
| 阶段 | 角色 | 模型 | 输入 | 输出 | 工具权限 |
|---|---|---|---|---|---|
| 1 | Planner(规划师) | Opus | 功能需求 | .pipeline/spec.md |
Read, Grep, Glob, Write |
| 2 | Coder(编码者) | Sonnet | spec.md | .pipeline/changes.md |
Read, Write, Edit, Grep, Glob, Bash |
| 3 | Tester(测试员) | Sonnet | changes.md + spec.md | .pipeline/test-results.md |
Read, Write, Edit, Grep, Glob, Bash |
| 4 | Reviewer(审查官) | Opus | 全部交接文件 + git diff | .pipeline/review.md(SHIP / NEEDS WORK / BLOCK) |
Read, Grep, Glob, Bash(只读) |
关键设计决策:
- Planner 和 Reviewer 用 Opus:规划决定质量上限,终审需要最强判断力
- Coder 和 Tester 用 Sonnet:执行明确指令时性价比最优
- 交接文件机制:每个 Agent 只读前一阶段的输出,保持上下文窗口干净
- Reviewer 只读权限:无法修改代码,只能评判,确保独立审查
- 编排器:单个
/shipslash command 串联全部 4 个 Agent,遇 OPEN QUESTIONS 或测试失败时暂停等人决策
落地路径:先跑 Planner + Coder 两阶段链,验证稳定后再接入 Tester 和 Reviewer。文章末尾推广了 Teamly 平台,提供托管式多 Agent 协调服务($29/月,5 个 Agent)。
Four AI agents can ship a feature while you sleep. Most people never wire them up.
They fire a reviewer here, a test generator there, by hand, one at a time, each forgetting what the last one did. You're still the bottleneck.
The fix: Planner → Coder → Tester → Reviewer, chained to hand off automatically. One trigger, four stages, a finished feature by morning.
Here's the full pipeline, with copy-paste code 👇
Before we dive in, I share daily notes on AI & vibe coding in my Telegram channel: https://t.me/zodchixquant 🧠
Why a pipeline beats a pile of agents
One agent doing everything fills its context window with planning, code, tests, and review notes until quality drops.
Four specialists each stay in a clean, narrow context.
The trick is the handoff file. Each agent writes its output where the next one can read it: Planner drops a spec at .pipeline/spec.md, Coder reads it and writes .pipeline/changes.md, and so on.
The orchestrator running them in order is a single slash command. That's the whole thing: four subagents, one command, a shared folder for handoffs.
Agent 1: The Planner (subagent, opus)
The Planner never writes code. It turns a vague feature request into a concrete spec the Coder can follow without guessing.
Create .claude/agents/planner.md:
---
name: planner
description: Turns a feature request into an implementation spec. Use as the first stage of the feature pipeline.
tools: Read, Grep, Glob, Write
model: opus
---

You are a planning specialist. You do NOT write implementation code.

Given a feature request:
1. Read the relevant parts of the codebase to understand current patterns.
2. Write a spec to \`.pipeline/spec.md\` containing:
   - Files to create or modify, with exact paths
   - The interface or function signatures needed
   - Edge cases the implementation must handle
   - Which existing patterns to follow (name the file to copy from)
3. Flag anything ambiguous as an OPEN QUESTION at the top of the spec.

Keep the spec tight. The Coder reads this and nothing else, so leave
no gaps and invent no requirements that weren't asked for.
Planning runs on opus because this stage sets the quality ceiling for everything after it. A vague spec produces vague code no matter how good the Coder is.
Agent 2: The Coder (subagent, sonnet)
The Coder reads the spec and writes the implementation. It doesn't plan and it doesn't review its own work, it just builds what the spec says.
Create .claude/agents/coder.md:
---
name: coder
description: Implements the spec at .pipeline/spec.md. Use as the second stage of the feature pipeline, after the planner.
tools: Read, Write, Edit, Grep, Glob, Bash
model: sonnet
---

You are an implementation specialist.

1. Read \`.pipeline/spec.md\` in full. If it has OPEN QUESTIONS, stop and
   surface them instead of guessing.
2. Implement exactly what the spec describes. Follow the patterns it
   names. Do not add features it didn't ask for.
3. Write a short summary to \`.pipeline/changes.md\`: which files changed,
   what each change does, and anything the Tester should focus on.

You write code that matches the repo. You do not refactor unrelated
code or "improve" things outside the spec's scope.
Sonnet is the right call here: implementation against a clear spec is exactly the balanced cost-quality work Sonnet handles best.
The handoff note at .pipeline/changes.md is what lets the Tester target the right surface instead of testing blind.
Agent 3: The Tester (subagent, sonnet)
The Tester reads what changed and writes tests that prove the feature works, then runs them.
Create .claude/agents/tester.md:
---
name: tester
description: Writes and runs tests for changes described in .pipeline/changes.md. Third stage of the feature pipeline.
tools: Read, Write, Edit, Grep, Glob, Bash
model: sonnet
---

You are a test specialist.

1. Read \`.pipeline/changes.md\` to see what was built and where.
2. Read the changed files and the spec at \`.pipeline/spec.md\`.
3. Write tests covering: the happy path, the edge cases the spec named,
   and at least one failure case. Match the repo's test framework.
4. Run the tests. If any fail, write the failures to
   \`.pipeline/test-results.md\` and STOP. Do not fix the code yourself.
5. If all pass, note that in \`.pipeline/test-results.md\`.

You test behavior, not implementation details. A failing test means
the pipeline pauses for the Reviewer, not that you patch around it.
Agent 4: The Reviewer (subagent, opus)
The last gate. The Reviewer reads everything the pipeline produced and gives a verdict before any of it reaches your main branch.
Create .claude/agents/reviewer.md:
---
name: reviewer
description: Final review of the full pipeline output. Fourth and last stage before human sign-off.
tools: Read, Grep, Glob, Bash
model: opus
---

You are a senior reviewer. You are read-only. You do not edit code.

1. Read the spec, the changes summary, and the test results from
   \`.pipeline/\`.
2. Run \`git diff\` to see the actual changes.
3. Assess: does the code match the spec? Are the tests meaningful or
   superficial? Any security, performance, or correctness issues?
4. Write a verdict to \`.pipeline/review.md\`:
   - VERDICT: SHIP / NEEDS WORK / BLOCK
   - For NEEDS WORK or BLOCK, list exactly what to fix and where.

Be the last line of defense. If the tests are green but the code is
wrong, say BLOCK. Green tests are not the same as correct behavior.
Read-only tools mean the Reviewer can't paper over problems by editing, it can only judge.
The orchestrator: one command to run all four
Now the piece that turns four separate agents into a pipeline. A slash command that invokes them in order, each one picking up the handoff file the last one wrote.
Create .claude/commands/ship.md:
Run the full feature pipeline for: $ARGUMENTS

Execute these stages in order. Do not skip ahead. After each stage,
confirm the handoff file exists before starting the next.

1. Delegate to the \`planner\` subagent with the feature request above.
   Wait for \`.pipeline/spec.md\`.
2. If the spec has OPEN QUESTIONS, stop and show them to me. Otherwise
   delegate to the \`coder\` subagent. Wait for \`.pipeline/changes.md\`.
3. Delegate to the \`tester\` subagent. Wait for \`.pipeline/test-results.md\`.
   If tests failed, stop and show me the failures.
4. Delegate to the \`reviewer\` subagent. Show me \`.pipeline/review.md\`.

Report the final verdict. Do not merge anything. Leave the branch for
my morning review.
Then a single line kicks off the whole chain: /ship add rate limiting to the login endpoint.
Where I run the overnight version
That's what I use Teamly for: managed cloud hosting built specifically for AI agents.
You hire a team, it runs 24/7 on dedicated infrastructure, and you never touch a server.
The reason @Teamly fits this article specifically: the handoff problem is already solved for you.
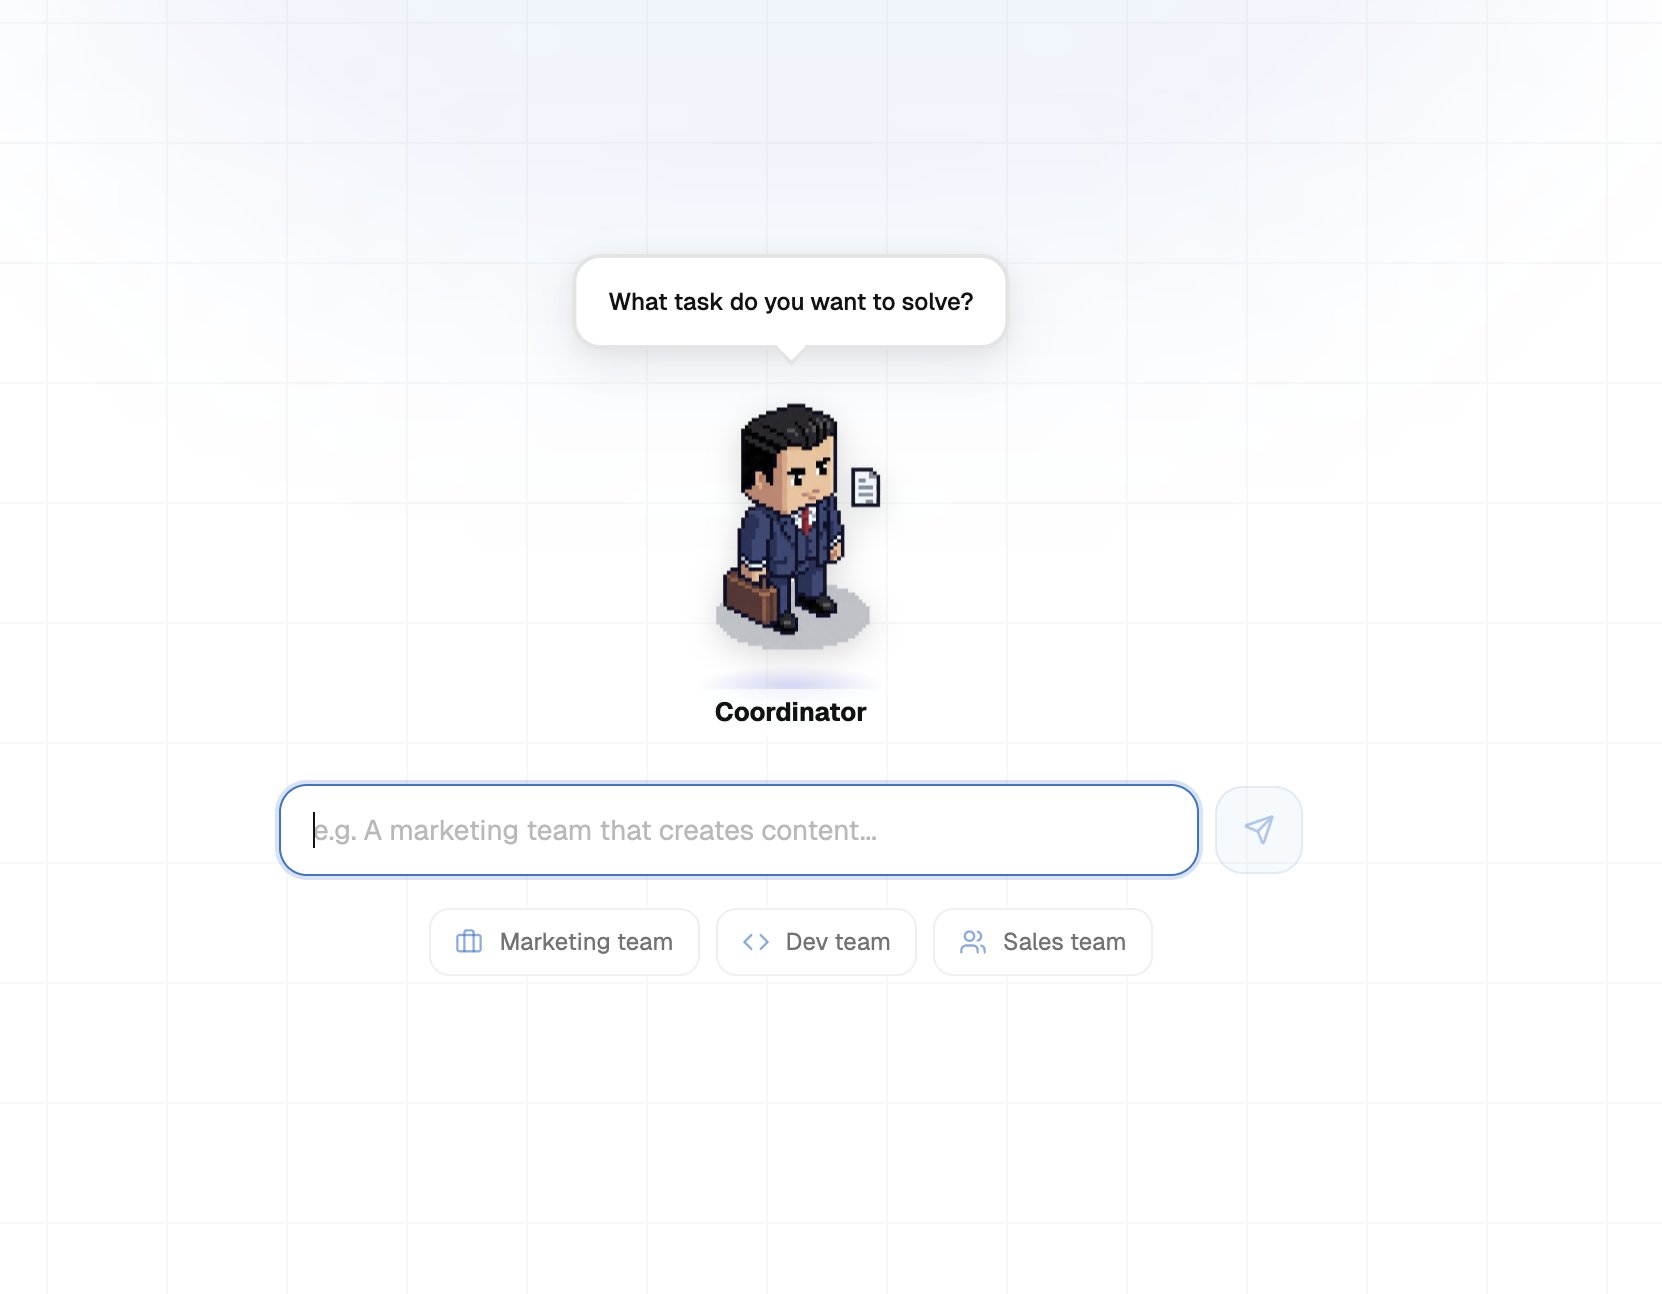
Everything we built by hand above (the spec file, the changes file, the orchestrator chaining one agent to the next) Teamly does with a Coordinator.
It routes work between agents, passes context from one to the next, and keeps a shared brief they all read from.
The same Planner-to-Coder-to-Tester flow, except you don't wire the handoffs yourself.
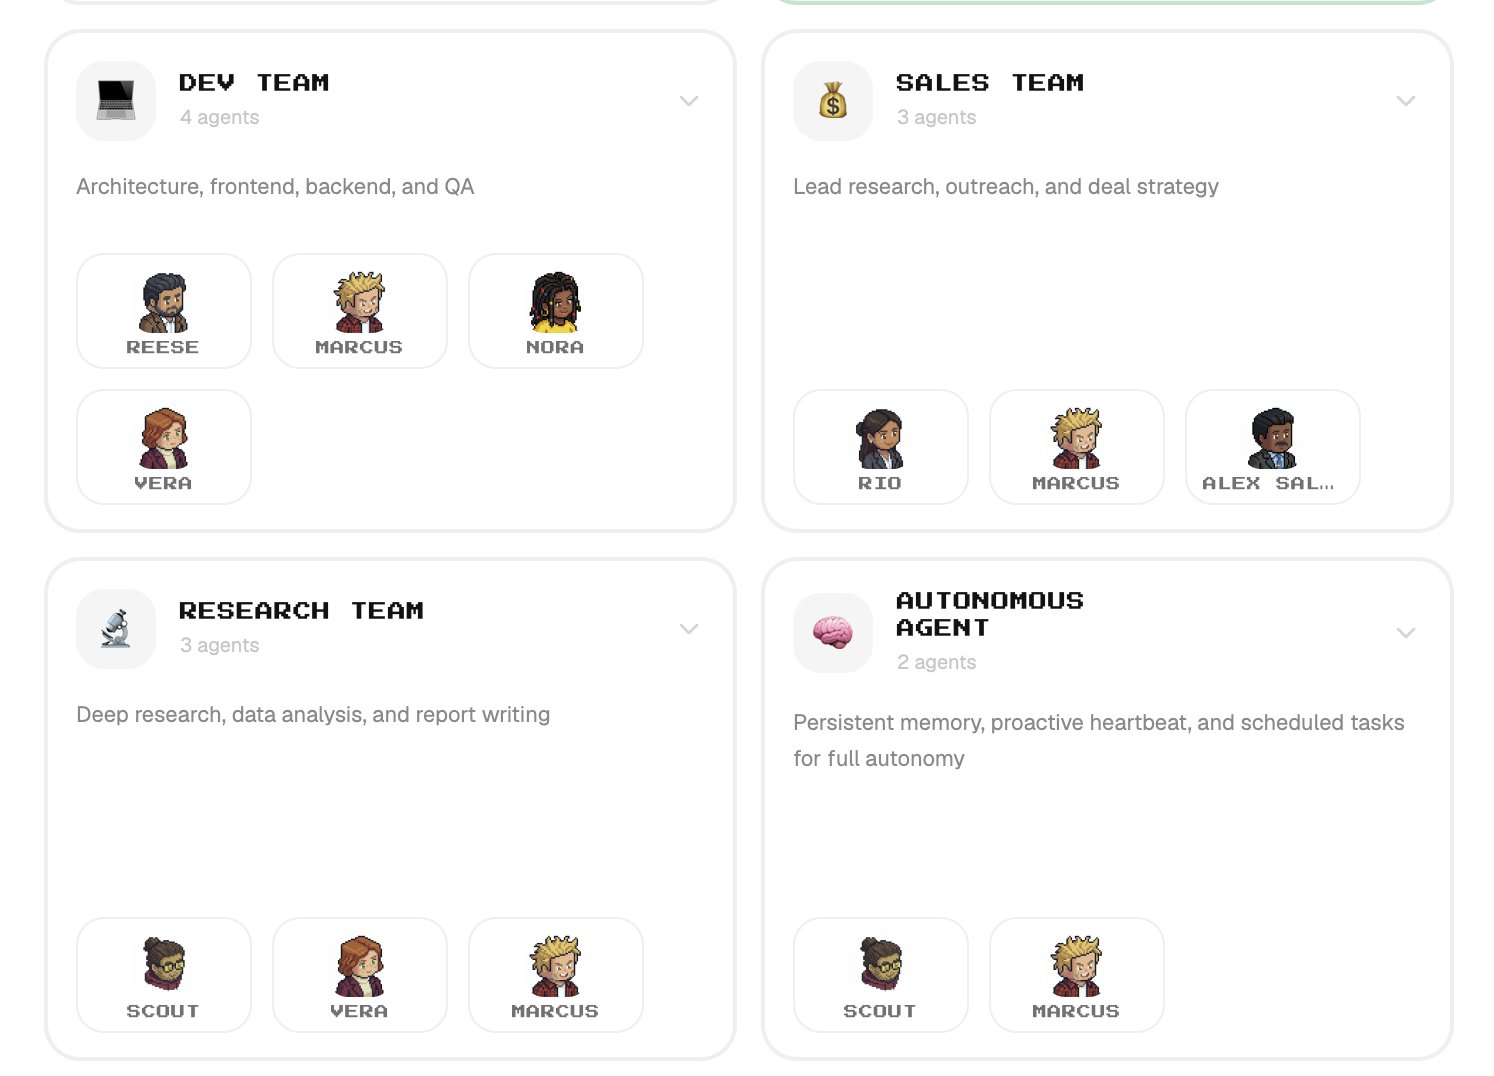
The difference is that @Teamly isn't code-only. The exact same orchestration runs a marketing team, a research team, or a support team.
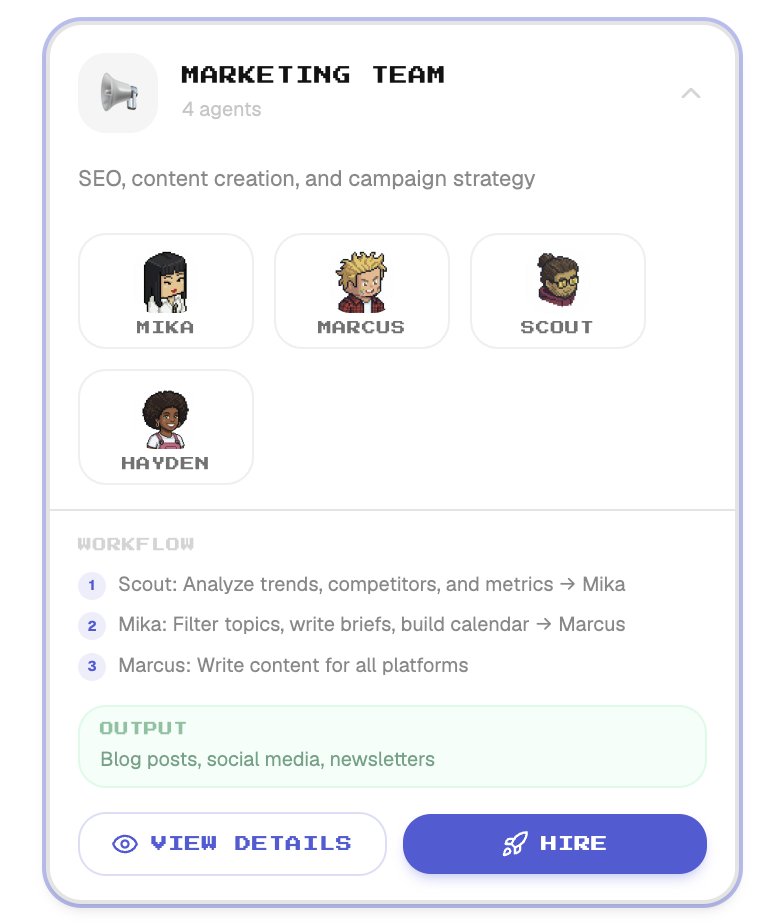
Your Claude Code pipeline ships features overnight; a Teamly marketing team ships content the same way, with the same hand-off logic underneath.
Build the exact team you need
New feature, that team just rolled out: My Team
Now you can build your team with just 3 questions.
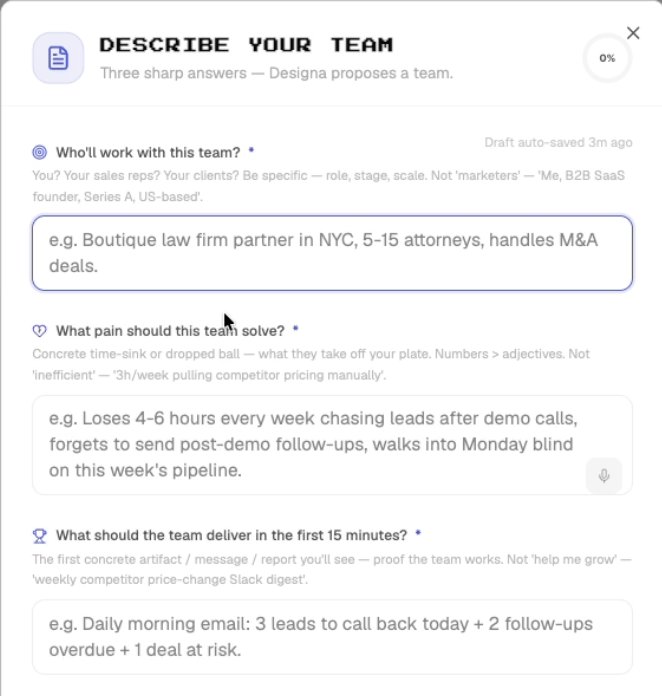
You also can control: voice rules, forbidden phrases, integrations, team style (Strict / Casual / Creative), and team size (2-4 agents).
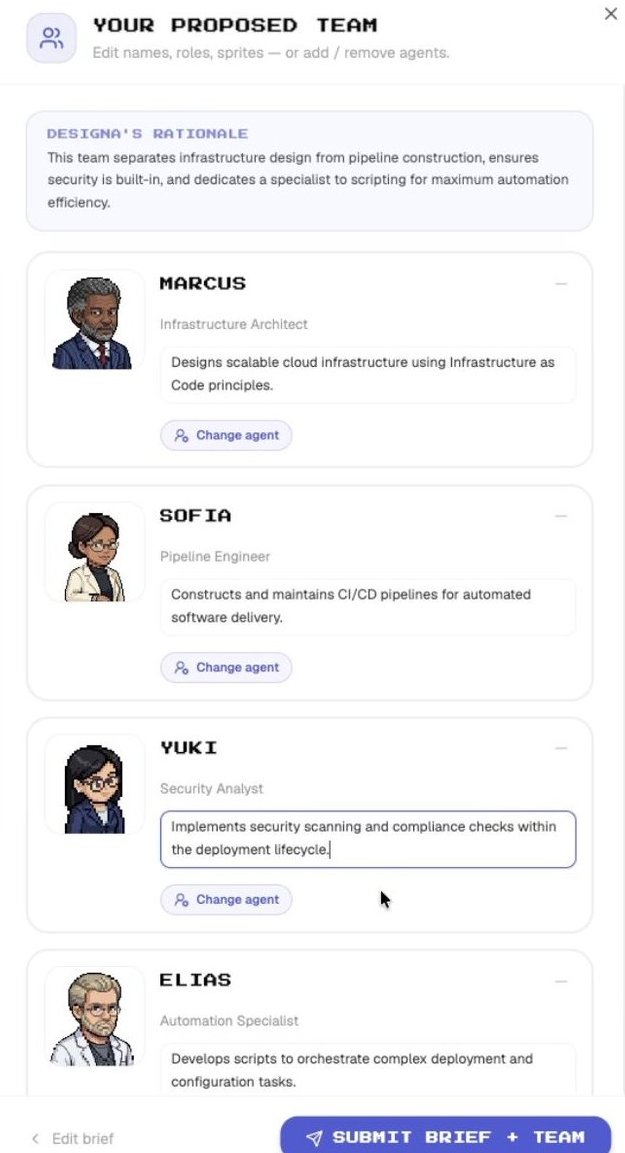
@Teamly returns a team with a real rationale for why each specialist is there, not boilerplate. Swap any agent with one click. Edit the brief if it's off.
The point is a structured brief that forces clarity, then composes a team you can audit before hiring.
Same handoff architecture as the pre-built teams, fitted to your specific problem.
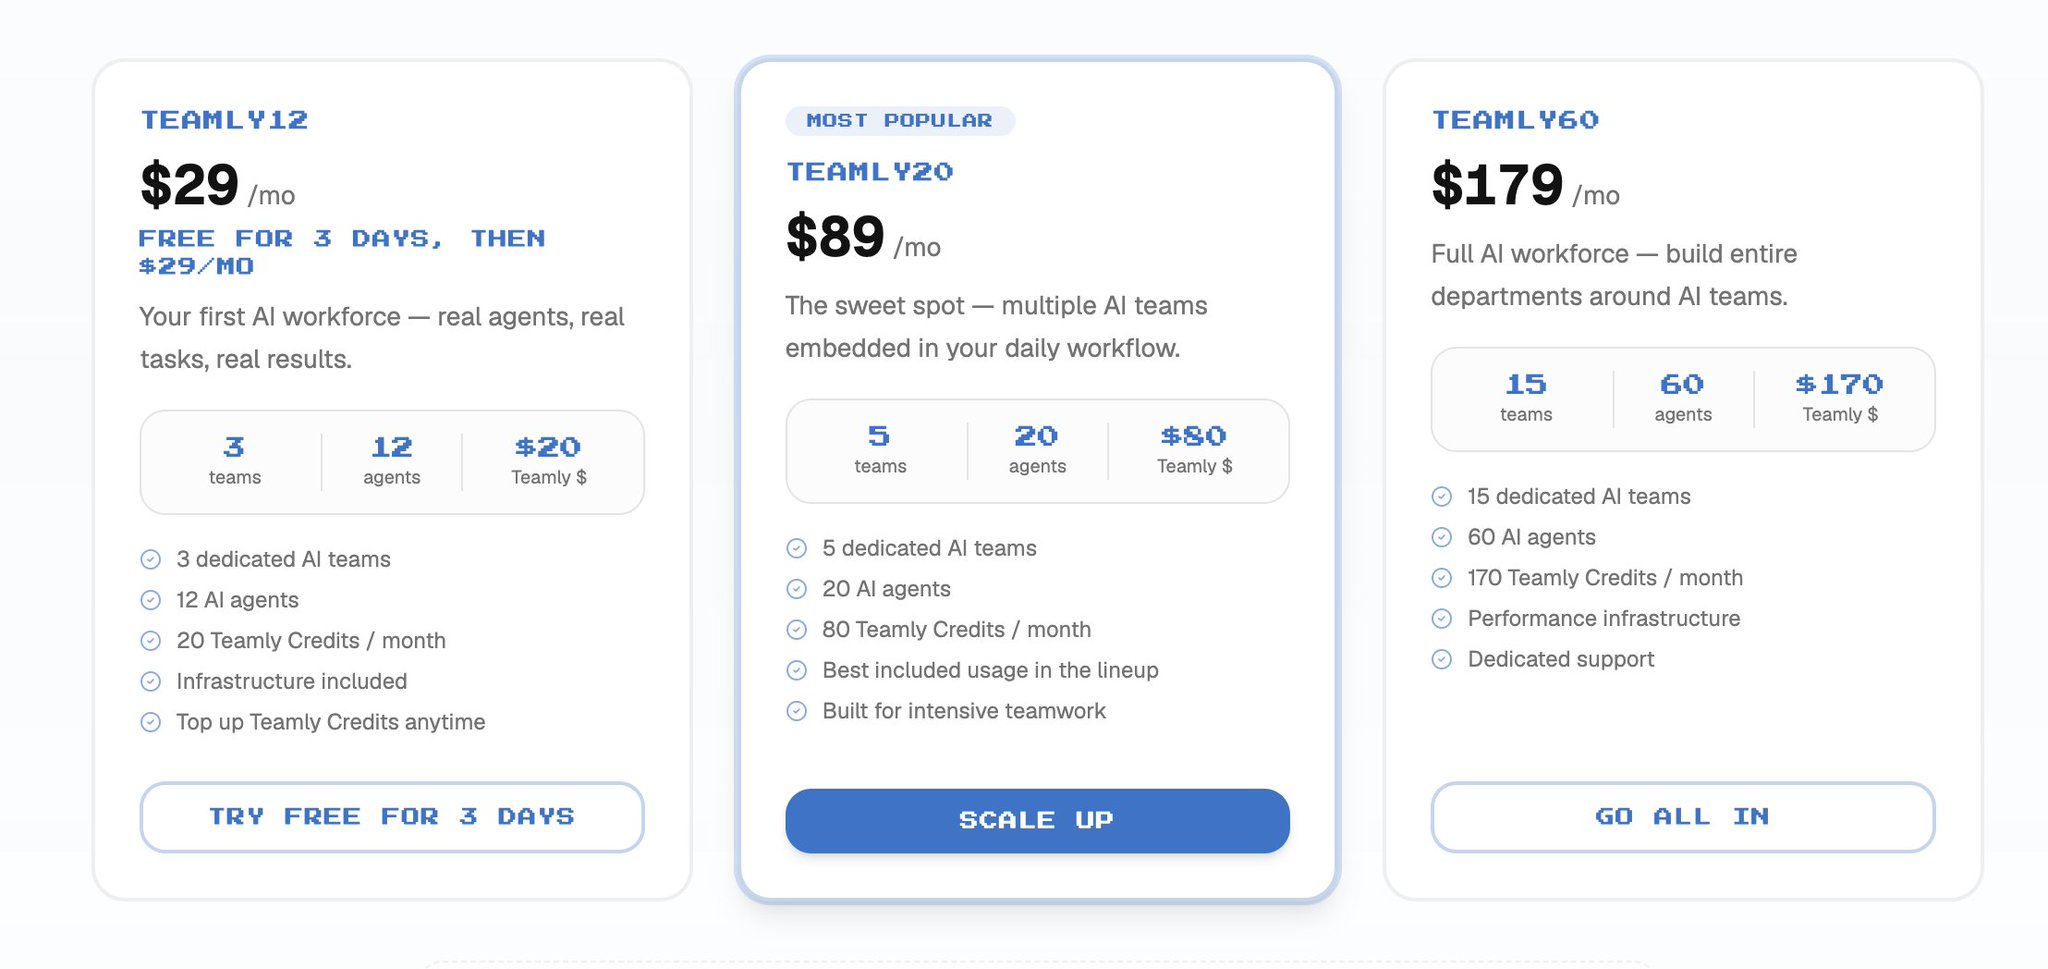
Try it free first
You can test the whole thing free for 3 days on Teamly 5, no charge until day 4.
If you stay, pricing is $29/mo for 5 agents.
Cheap enough that one shipped feature pays for the month.
The bottom line
The difference between a pile of agents and a pipeline is the handoff.
Four specialists writing to shared files, one orchestrator running them in order, each stage building on the last instead of starting from scratch.
Build the Planner and Coder first and run them as a two-stage chain. Once that flow feels solid, add the Tester and Reviewer.
By the time all four are wired up, you'll kick off a feature before bed and read a verdict with your coffee.
For daily notes on AI agents, vibe coding and Claude Code setups: https://t.me/zodchixquant 🧠