Eval Engineering: build the gate that lets your agents merge without you (full 6-step course)
The end state is easy to describe. An agent finishes a change, opens it, and it goes in without a human reading it.Not because anyone decide...
📝 摘要
本文系统阐述了如何构建一个自动化评估门控(gate),使 AI Agent 的代码变更可以在无需人类审查的情况下安全合入。文章指出,大多数团队缺少这个门控,不是因为勇气不足,而是因为门控所需的证据基础尚不存在。作者提出了 6 个步骤来逐步建立这一体系:Step 1 揭示 LLM-as-Judge 存在系统性偏差(自我偏好、冗长偏好),同一输出在不同评委下评分可从 93.3% 暴跌至 39.5%,需跨家族评委、多评委面板、以及将客观检查交给代码;Step 2 强调 verdict 必须驱动运行行为(thermostat vs thermometer),而非仅停留在仪表盘;Step 3 主张评估路径而非仅评估最终答案,需三层评估(端到端/轨迹/组件)和三个核心指标(Faithfulness/工具参数准确性/任务完成度);Step 4 提出从日志中挖掘测试用例,将真实失败转化为永久测试;Step 5 要求锁定评委版本、避免 Goodhart 定律陷阱,并引用 ICLR 2024 证明无外部锚定的自我修正不可靠;Step 6 提出基于爆炸半径(blast radius)而非置信度开放门控,按可逆性分三车道,先影子模式运行再逐步放开。
核心概念: 构建一个约束足够紧的自动化门控,让信任不再是问题——门控读证据而非意见,评估路径而非仅看答案,未转化为永久测试的失败终将再次出现。
关键技术栈 / 关键要点:
- LLM-as-Judge 偏差 — 同家族评委存在自我偏好偏差(GPT-5.2/Gemini 3.1 Pro 给本家族 75-84% 胜率),需跨家族评委面板打破相关性错误
- Verdict 驱动运行 — 低 grounding 拒绝交接、schema 失败阻断边、疑似编造隔离分支,eval 应内嵌于 agent 而非事后报告
- 轨迹评估三层模型 — 端到端(任务是否成功)、轨迹层(路径是否合理,检测循环/冗余)、组件层(哪个 retriever/tool/sub-agent 损坏)
- Faithfulness 指标 — 答案是否基于工具实际返回而非模型编造,是最隐蔽的失败模式
- 日志挖掘测试 — 从 traces 中提取干净/纠正/空返回/超时四种运行,将失败归因到 agent 或依赖,并测试验证器本身
- 评委版本锁定 — 静默升级评委使分数不可比,rubric 应写成一行可独立验证的结果,绝不奖励答案的"形状"
- 爆炸半径门控 — 按可逆性分三车道(可逆隔离/可逆广泛/不可逆),门控读证据优先级:确定性检查 > eval 轨迹 > 历史回滚率 > 模型自评
关键结论 / 实践建议: 先以影子模式运行门控(评分但不合并),追踪门控与人类审查的分歧率,在分歧率显著高于零时保持关闭;评测套件至少 500 条用例,运行时间不超过一杯咖啡,否则沦为季度仪式。
The end state is easy to describe. An agent finishes a change, opens it, and it goes in without a human reading it.
Not because anyone decided to trust the model. Because a gate read the evidence and had a rule for it.
Almost nobody has that gate, and the reason is not courage.
The evidence it would need to read does not exist yet in most systems.
Here is what has to be true before you can open it, in six steps.
Step 1 - the score you are reading is partly about your judge
Automated evaluation started from a solid result.
Zheng and colleagues at UC Berkeley showed in 2023 that GPT-4 agreed with human raters over 80% of the time, roughly the rate at which humans agree with each other. The industry moved to API calls almost overnight.
What the follow-up work found is that judges respond to things other than the content in front of them.
Frontier judges systematically inflate scores for outputs from their own model family.
In one 2026 benchmark, GPT-5.2 and Gemini 3.1 Pro handed 75 to 84% win rates to their own families. Claude Opus 4.7 went the other way and under-rated its own family at 10.6 to 41.2%.
On ArenaHard the measured bias across judges spans from -38% to +90%.
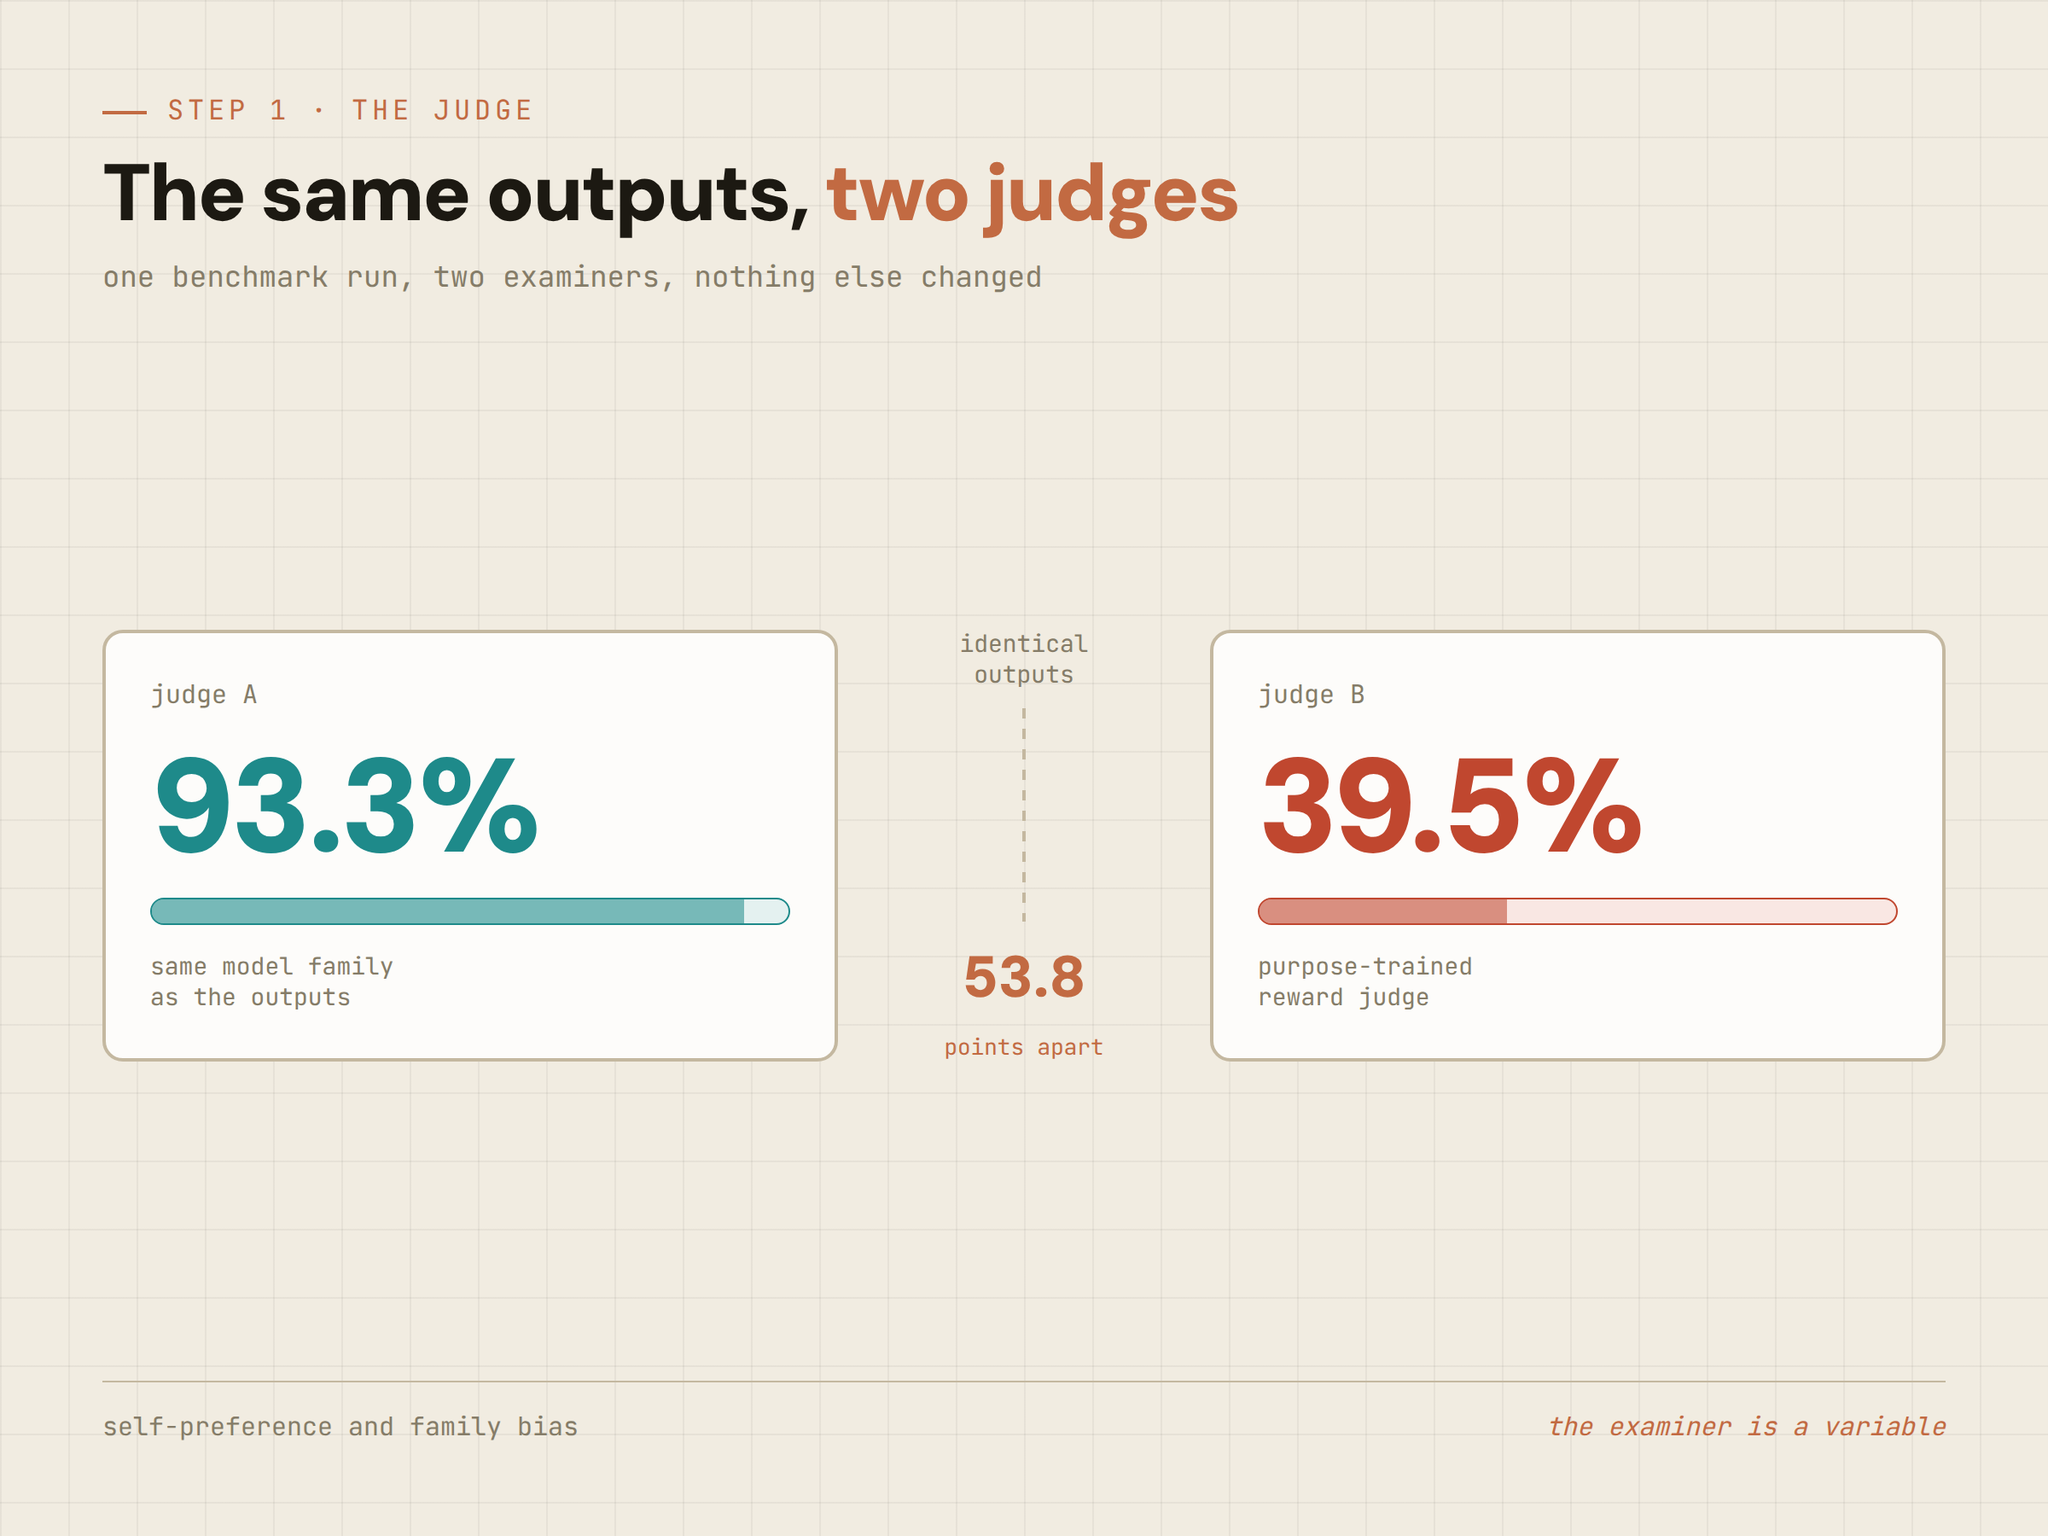
The same benchmark ran one set of outputs past two different judges. Under one, the model scored 93.3%. Under the other, the identical outputs scored 39.5%.
Verbosity bias runs alongside it: judges reward length whether or not the extra words carry information.
None of this makes the method useless. It makes the setup load-bearing, and three rules cover most of it:
- Judge from a different model family than the one generating. Same family means shared blind spots.
- For anything high-stakes, use a panel of judges from different vendors instead of one. Averaging across families is what breaks correlated errors.
- Anything objectively checkable goes to code, not to a judge. Did the test pass, does the file exist, did the state change.
A gate fed by a biased judge is worse than no gate.
It launders a guess into a number and then acts on it.
Step 2 - a verdict that does not change the run is a report
Most teams stop one step short.
They get a number, put it on a dashboard, and the dashboard changes nobody's behavior.
The shift that matured in 2026 is running evals inside the agent rather than after it. Pre-production evaluations get promoted into production guardrails, and the score controls what the agent may do next: which tools it can reach, whether a handoff is accepted, whether the run escalates to a person.
That is the difference between a thermometer and a thermostat.
Each verdict maps to a structural action on the run in progress.
Low grounding rejects the handoff.
A schema failure blocks the edge.
A suspected fabrication quarantines that branch instead of letting it merge into the main thread.
Verified completion is the only thing allowed to end the run.
An agent that stops calling tools has ended its turn. That is not the same as finishing the task, and only an external check knows the difference.
This is the first thing the gate reuses. A system where verdicts already steer runs has verdicts worth reading at merge time.
Step 3 - grade the path, not just the answer
Grading only the final response is how an agent reaches a correct answer through a broken sequence and nobody notices for a month.
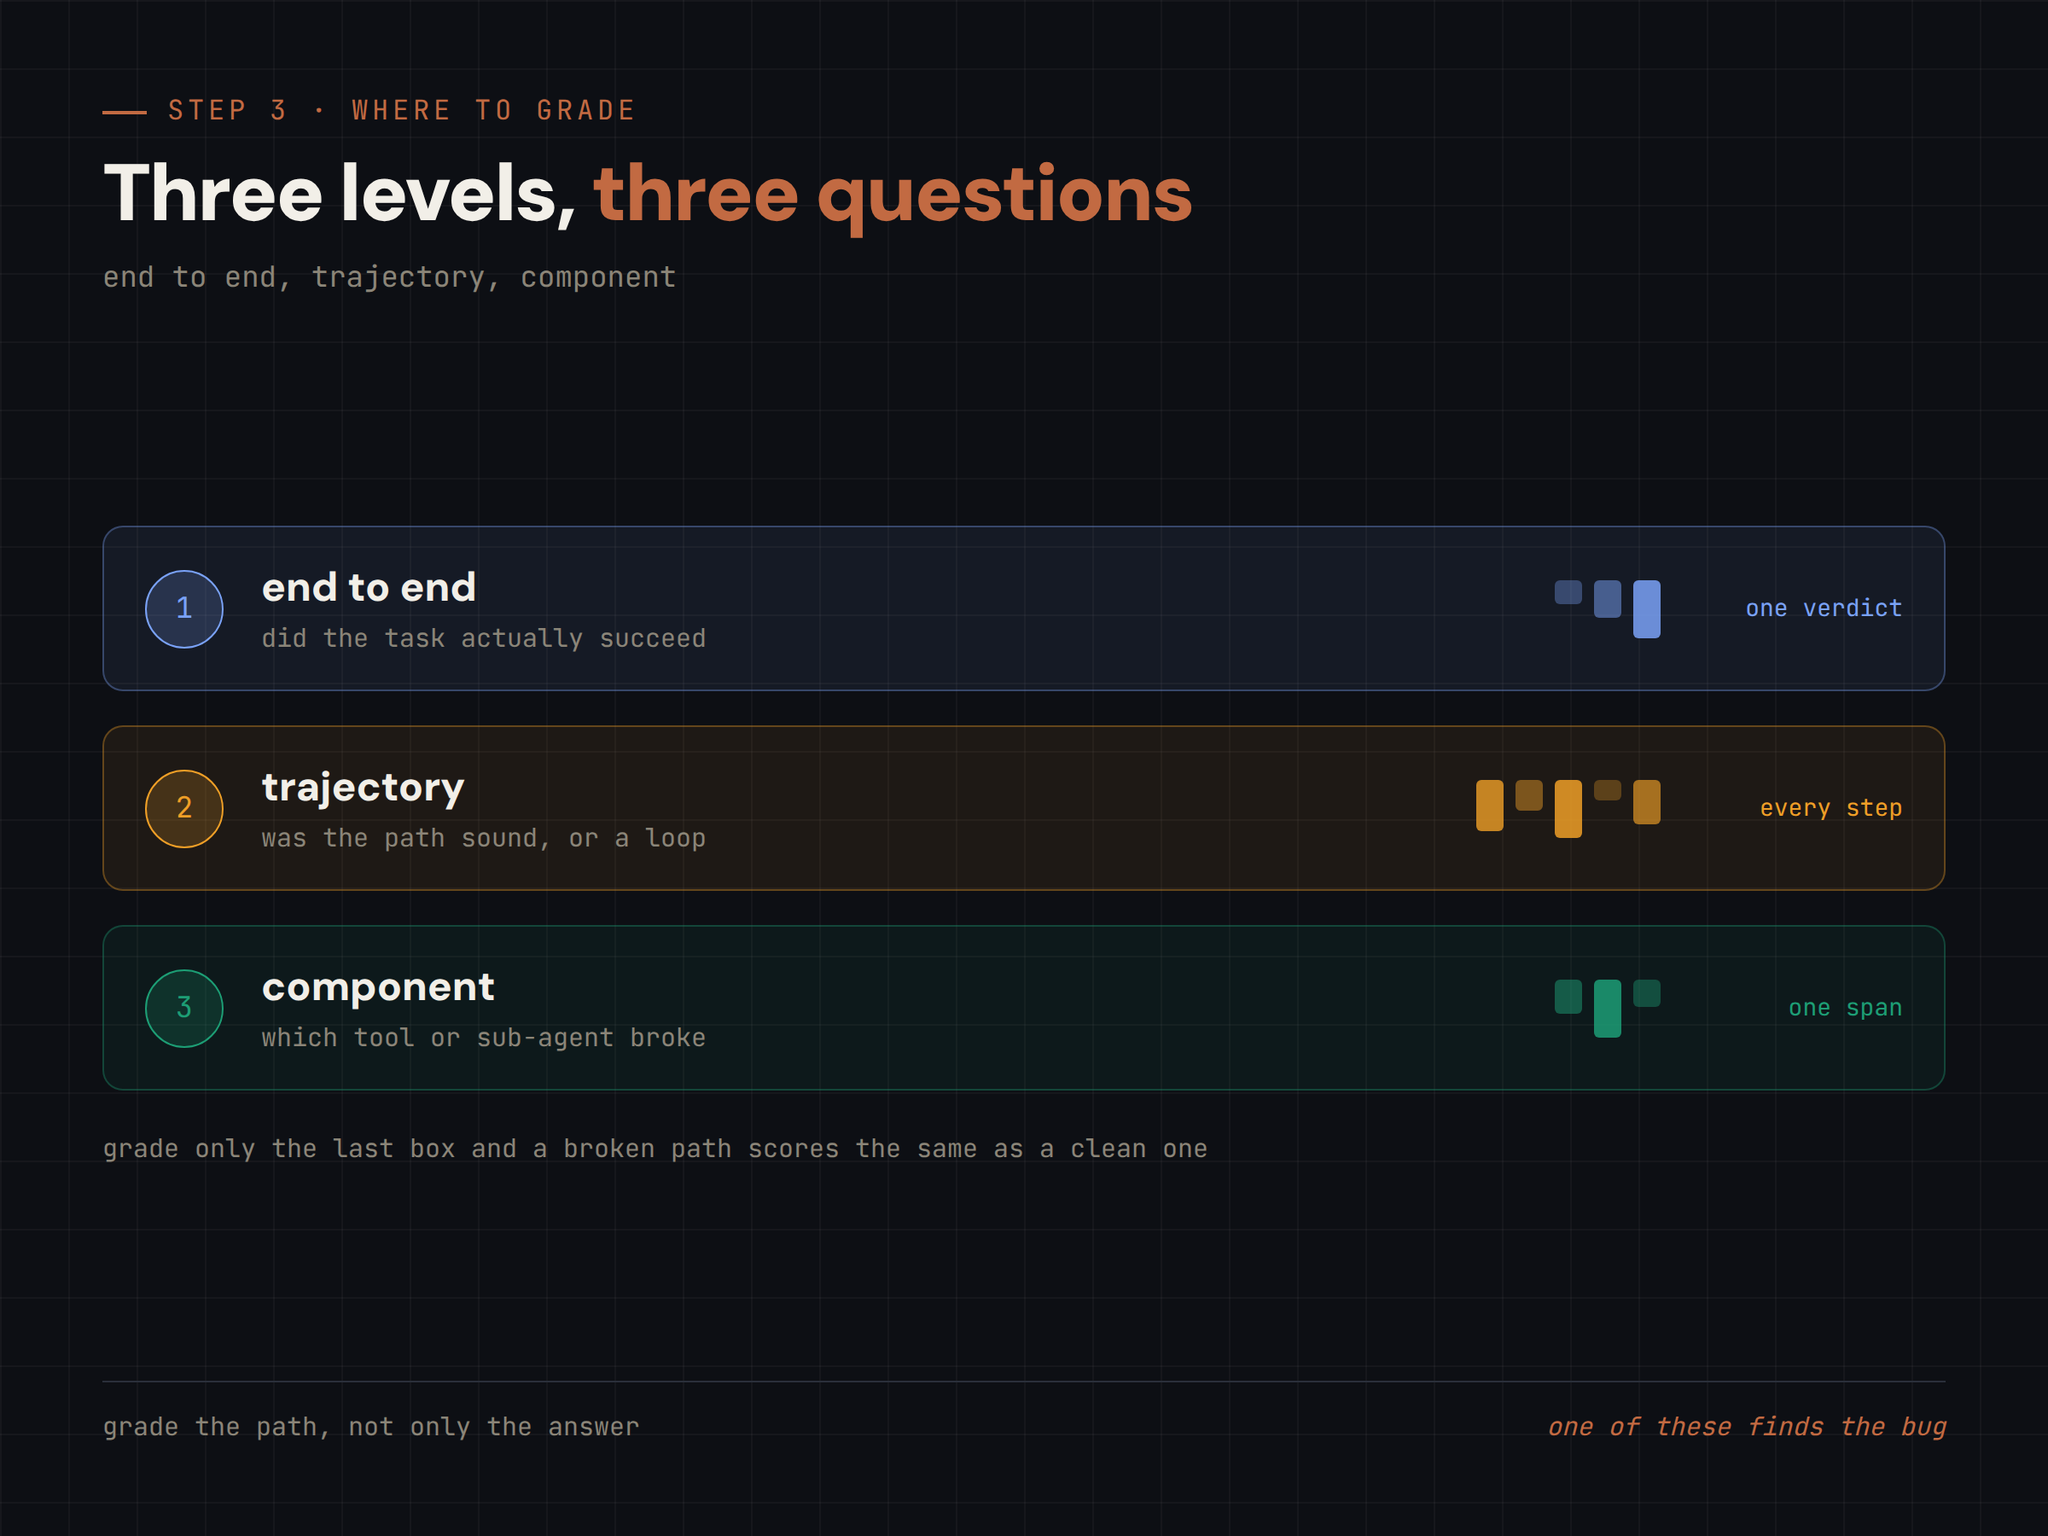
Agent evaluation splits into three levels and you need all three.
End to end asks whether the task succeeded.
Trajectory level asks whether the path was sound, which is where loops, redundant calls and wasted steps surface.
Component level asks which retriever, tool or sub-agent broke. It is the only level that tells you where to go and fix something.
Three metrics are enough to start.
Faithfulness, meaning the answer is grounded in what the tools actually returned rather than in what the model filled in when a tool came back empty.
Tool parameter accuracy, meaning right tool with right arguments.
Task completion, judged against a real signal rather than the agent's own claim.
Faithfulness is the one that hides. An agent that writes cleanly and invents an exchange rate scores well on every quality metric on your board, and the invention only surfaces when a customer acts on it.
For the gate, trajectory matters more than the final answer.
A change that arrived through a clean path is a different risk from an identical change that arrived after forty steps of thrashing, even when the diff looks the same.
Step 4 - your best tests are already in your logs
Tests you invent at a desk protect you from failures you already imagined.
The expensive ones are sitting in your traces right now, with a timestamp on them.
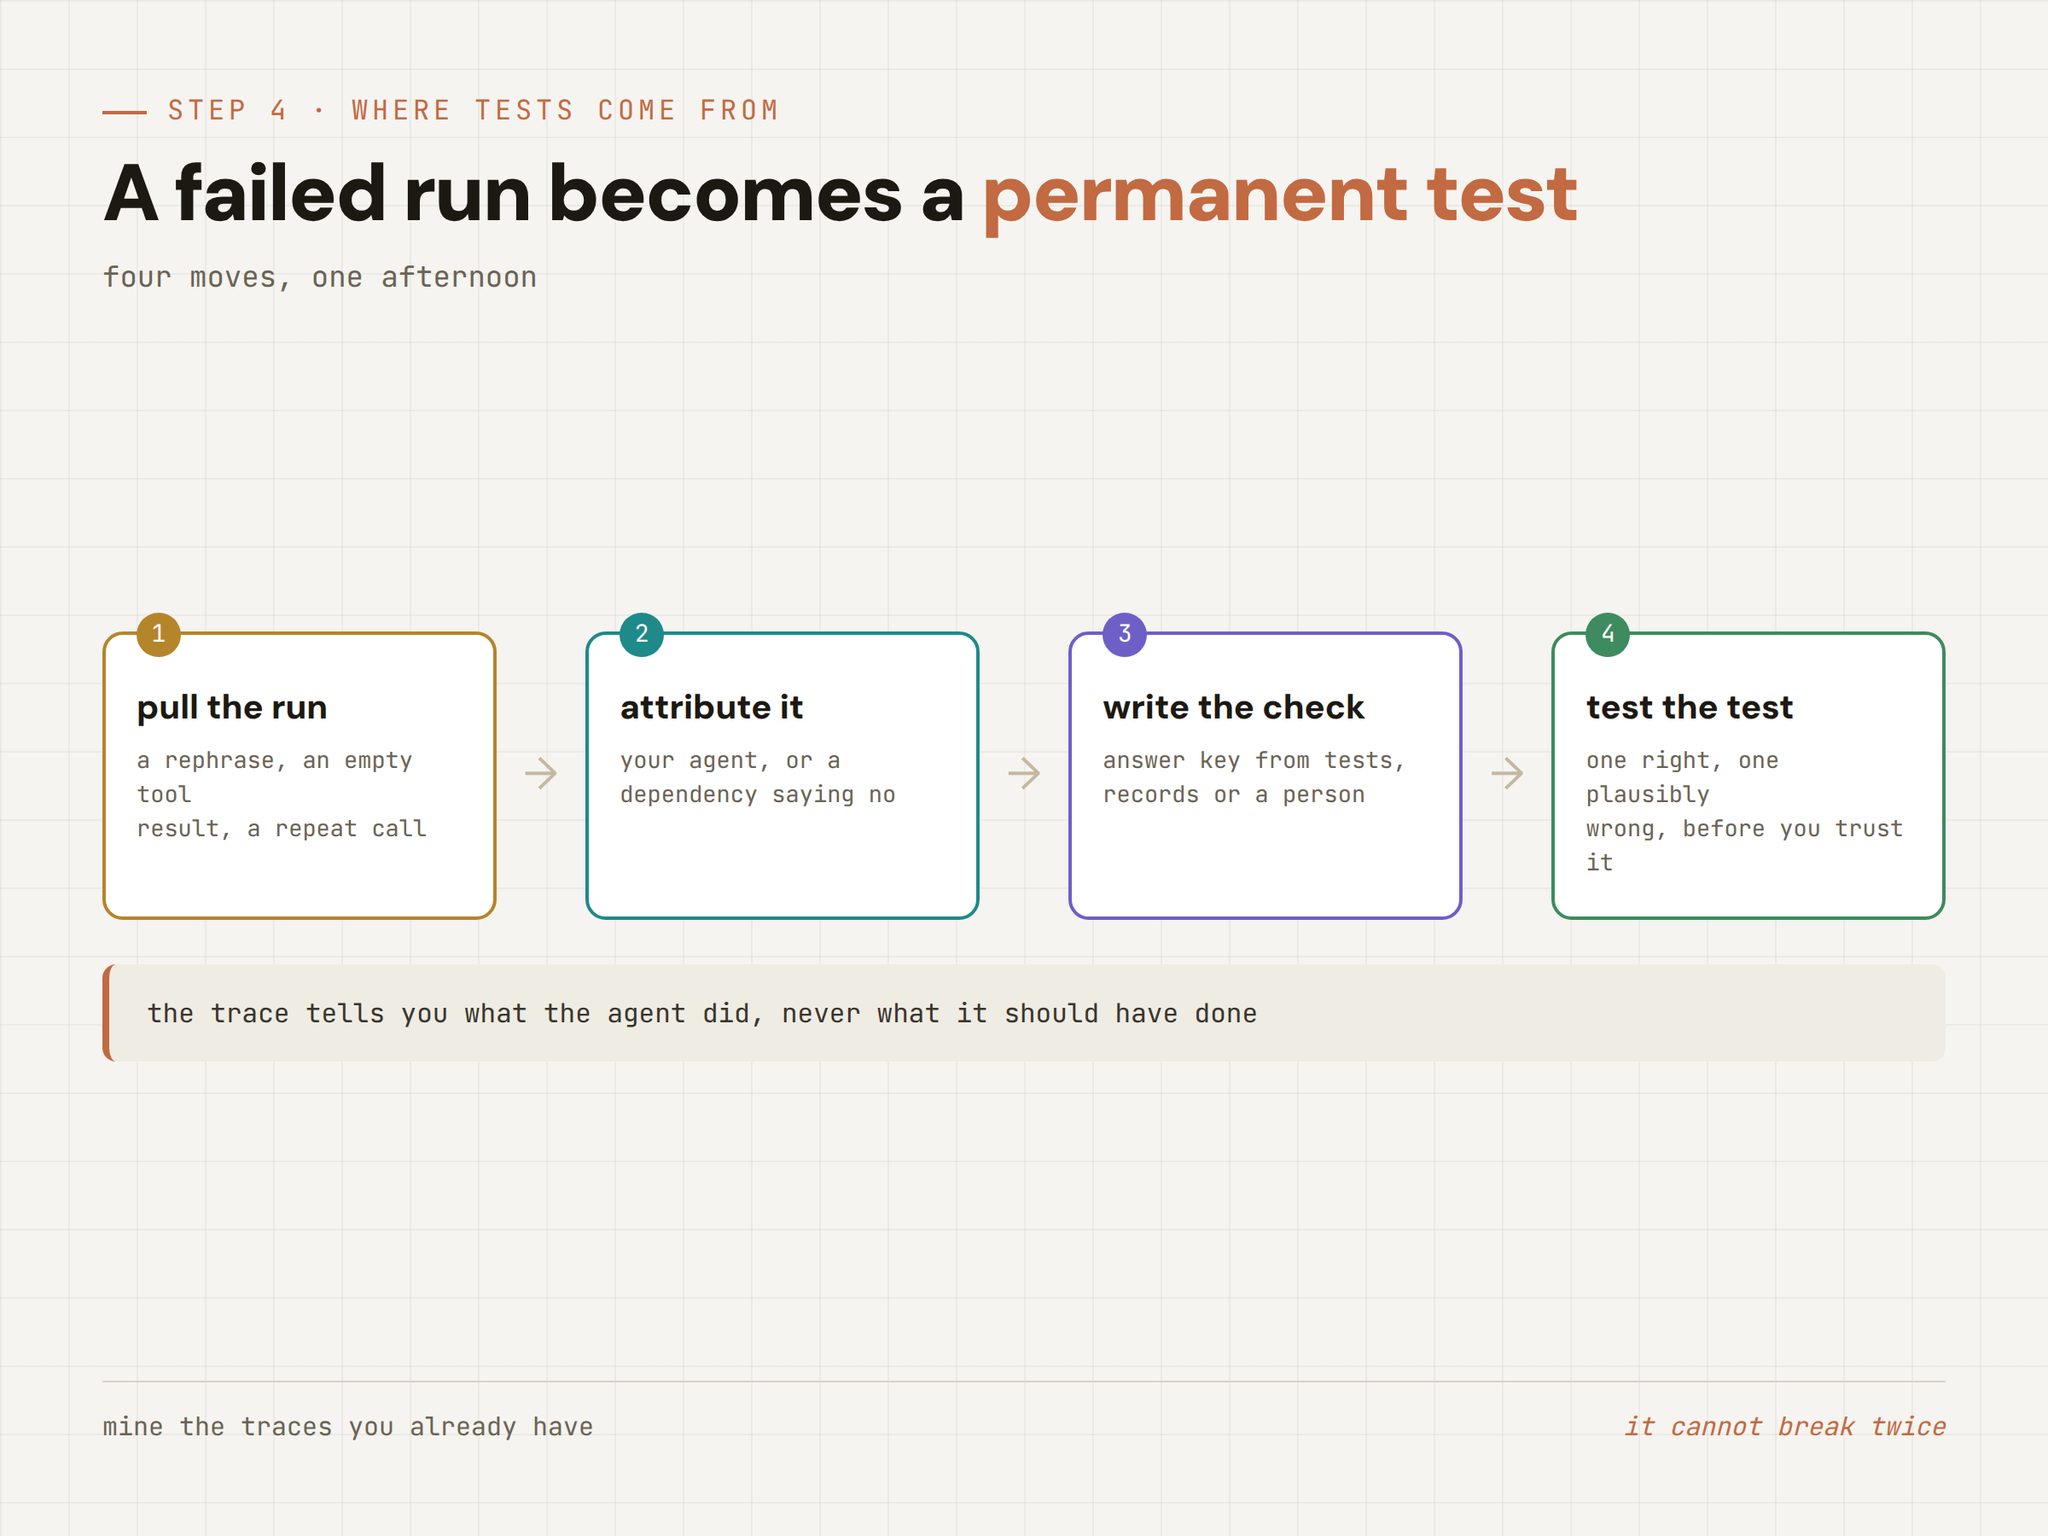
Pull a small set of complete runs and pick them so working and broken behavior sit next to each other:
A request that finished cleanly, as your baseline for what working looks like.
A request the user rephrased or corrected, because the correction is a free label.
A run where a tool returned empty, or got called twice with identical arguments.
A run where something external timed out, where the only thing tested is how your agent behaves when the world says no.
Write each one up in four lines: what the agent did, what worked and what did not, whether the cause was your agent or a dependency, and which capability the eval should protect.
Attribution is where people lose a week.
The same lookup twice with identical arguments is a loop in your agent.
A rate limit coming back is somebody else's problem, and it only becomes your eval if your agent was supposed to recover from it.
Two rules keep this honest.
The trace tells you what your agent did, never what it should have done, so the answer key comes from tests, records, policy or a person.
And test the verifier before trusting it. Feed it one clearly correct result and one plausible wrong one. If either goes the wrong way, the rubric is broken, not the agent.
Every failure converted this way is something the gate cannot be surprised by twice.
Step 5 - pin the judge or lose the month
Judges are software with versions.
A judge that silently upgrades makes every score before and after incomparable.
The failure is quiet. The judge bumps a minor version one month and a major version the next, your suite keeps producing numbers, and those numbers stopped meaning the same thing weeks ago.
Pin the version and log it with every score.
Write the rubric as one line, in the form of pass if the independently observable outcome happened, rather than a bundle of proxy scores.
And never reward the shape of an answer. No points for length, keyword presence, citation count or similarity to a reference.
That last one is not a style preference.
Optimize hard enough against a judge and the agent learns to look right instead of be right, which turns your defense into an attack surface. Goodhart's law with a model in the loop.
One more thing worth knowing before you lean on self-review.
Huang and colleagues at DeepMind showed at ICLR 2024 that intrinsic self-correction, asking a model to review and revise its own work with no external grounding, does not reliably help and often makes things worse.
The grounding has to come from outside the model.
Size the suite so it survives contact.
The 2026 working guidance is at least 500 cases before trusting an aggregate number, and a run short enough that nobody plans around it.
A suite that takes longer than a coffee break becomes a quarterly ritual.
Step 6 - open the gate on blast radius, not on confidence
Here is where most write-ups go wrong.
They build a confidence score, set a threshold, and let anything above it through.
Confidence is the weakest variable in that decision.
The strong one is what happens if the change is wrong.
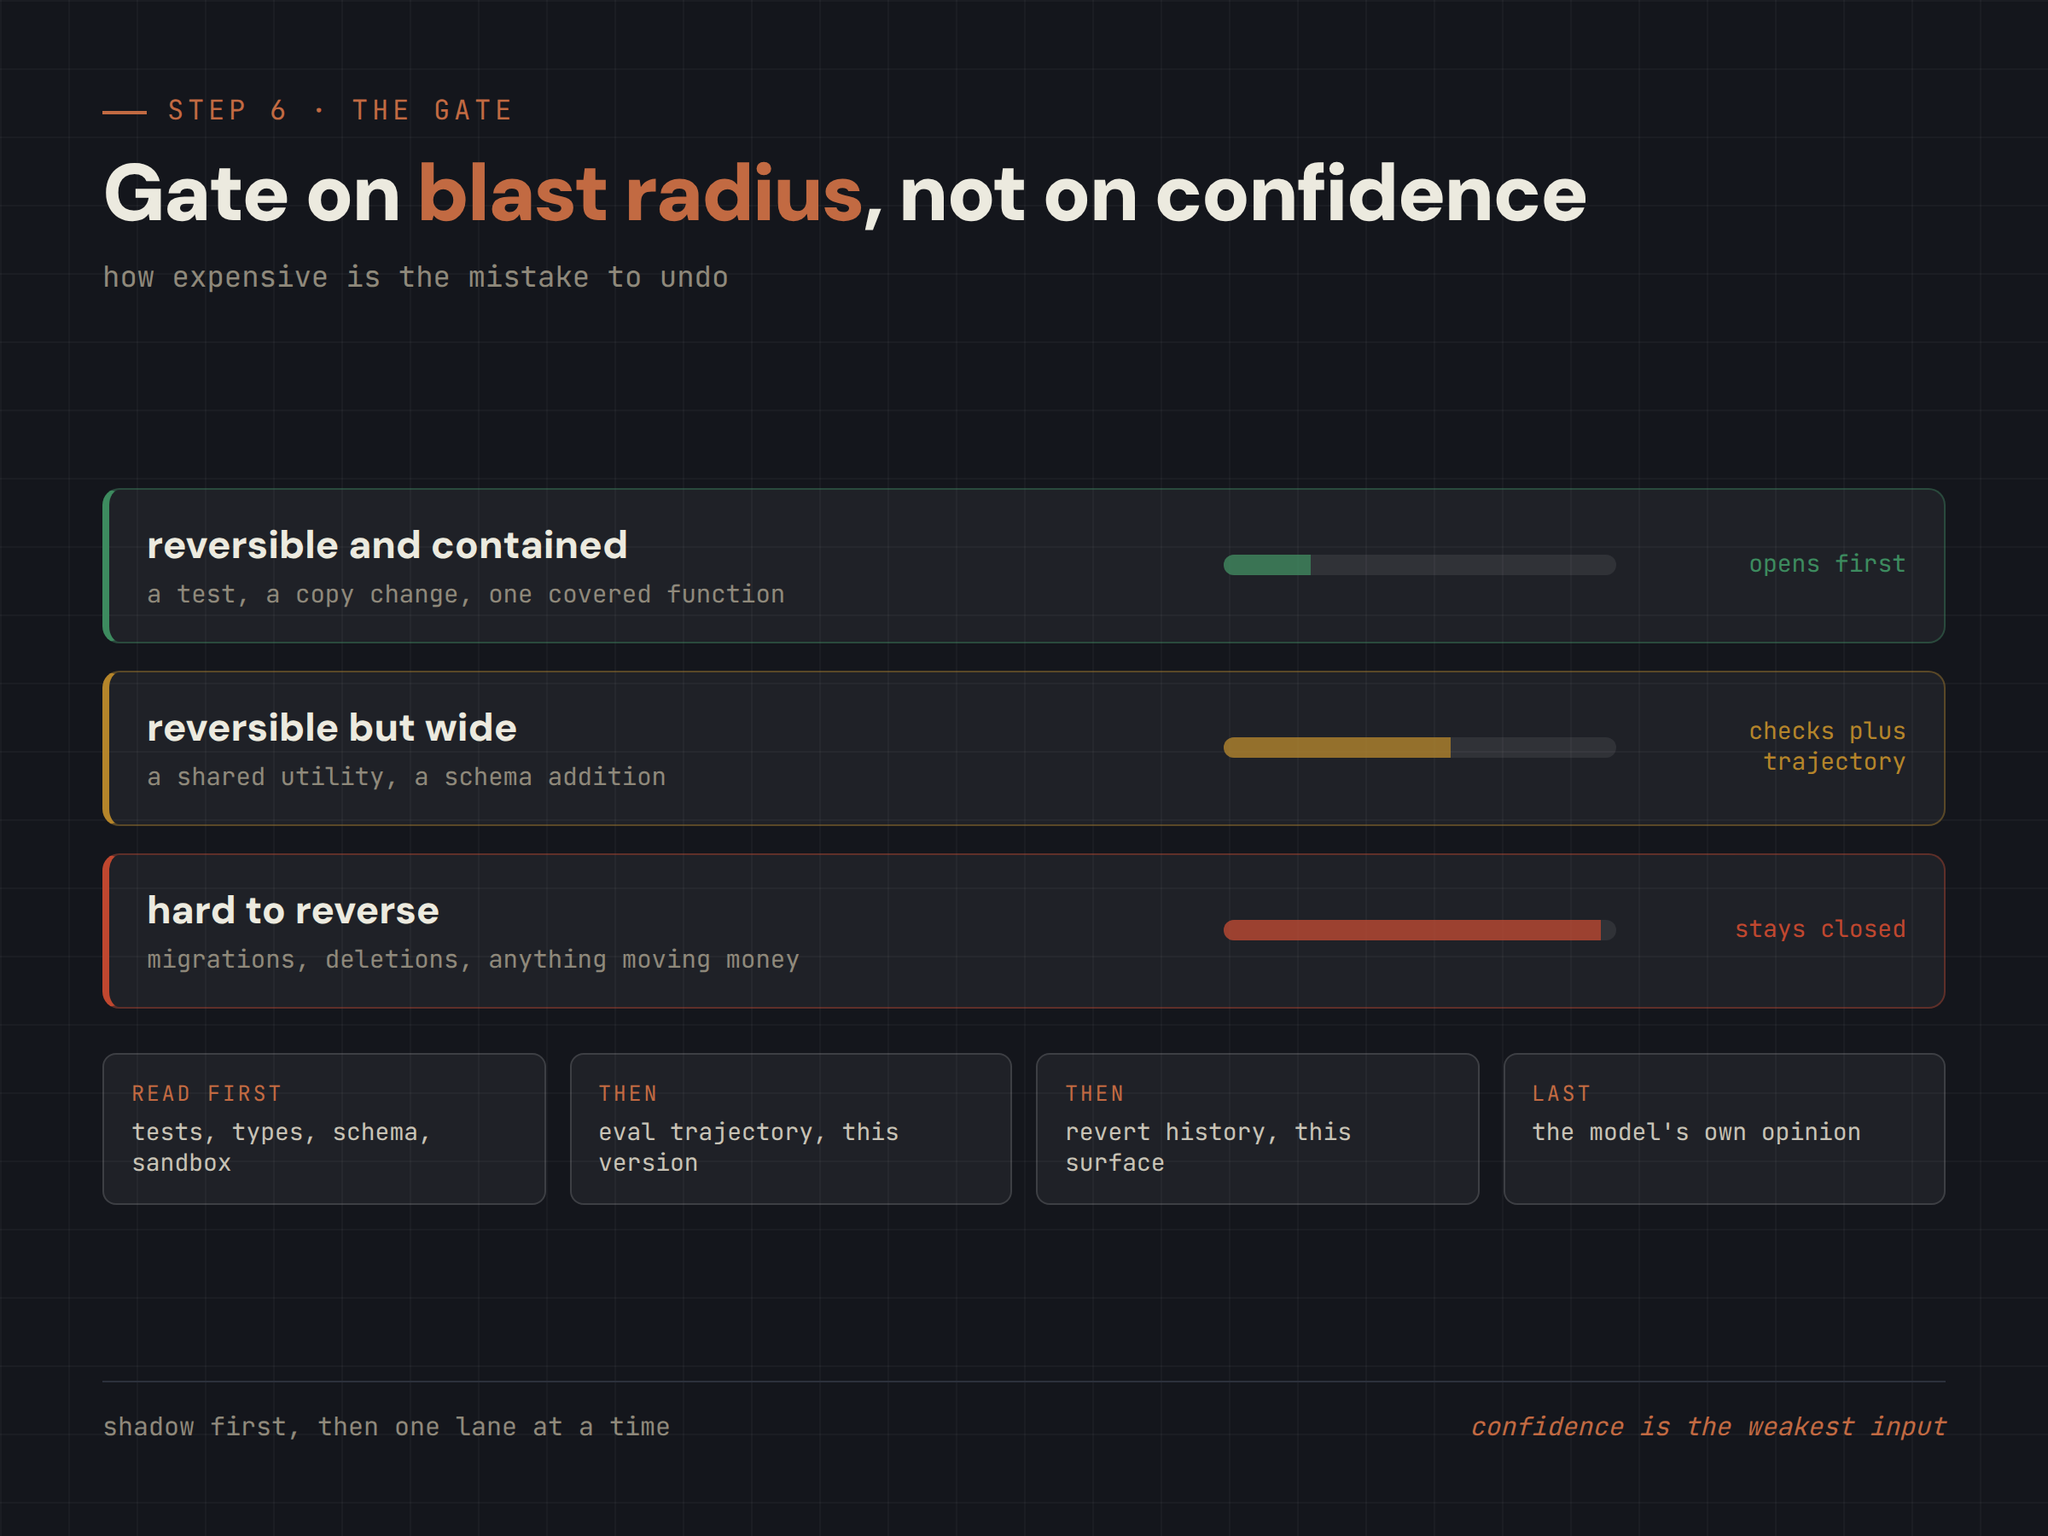
Sort work by how expensive the mistake is to undo, and gate each lane differently:
- Reversible and contained. A copy change, a test, an isolated function with coverage. One bad merge costs a revert. This lane can open first.
- Reversible but wide. A shared utility, a schema addition, anything a dozen callers touch. Gate this on the deterministic checks plus a clean trajectory.
- Hard to reverse. Migrations, deletions, anything that writes to production data or moves money. This lane does not open, regardless of score.
Inside an open lane the gate reads evidence, not opinions.
Deterministic results first, because no model is involved: tests, types, schema, sandbox execution.
Then the eval trajectory for this agent version.
Then the history, meaning how often work from this agent on this surface has been rolled back before.
The model's own assessment is the one input the gate should weight least, because it is the only one the model can influence.
Turn it on carefully.
Run in shadow first, where the gate scores every change and merges none of them, until you have enough real traffic to compare against.
Track how often the gate and the human reviewer disagree, and keep it closed while that number is meaningfully above zero.
And keep one warning in view. A suite can go entirely green while the product it guards falls apart, because the tests converge on the tests rather than on the spec.
Green is evidence, not proof.
The honest version of what you are building is not trust in the agent.
It is a constraint tight enough that trust stops being the question.
Three lines hold the discipline.
Measure the path, not only the answer it landed on.
A verdict that does not change what runs next is a report.
Any failure you do not turn into a permanent test, you will meet again.
The model on your card statement is a rental. The examiner around it is the only part you keep.
Follow me for more on agent internals, and subscribe to my Telegram channel: