What Is Reasoning
A short summary of how reasoning traces work.
📝 摘要
Armin Ronacher 在本文中深入剖析了 LLM 推理跟踪(reasoning traces)的内部工作机制,澄清了 Twitter 上关于"提取隐藏推理"的诸多误解。推理跟踪本质上并非特殊机制——它只是模型被训练后在特定标记(special tokens)之间的草稿板(scratchpad)文本,由解析器路由到独立流。文章以 GPT-OSS 的 Harmony 响应格式为例,展示了 analysis 通道与 final 通道的分离机制。推理强度(reasoning effort)也非采样过程属性,而是直接写入系统提示词的文本指令(如 Reasoning: low),由训练产生对应行为。禁用思维则是通过"机械移除"模型思考途径实现——如预填充 </think> token 关闭思维,或阻止采样推理 token。这解释了为何自定义 think 工具能在原生推理关闭时欺骗模型泄露推理内容。文章结尾幽默地提到,GPT 5.6 terra 的安全过滤器甚至阻止了对本文的语法检查。
核心概念: LLM 的推理跟踪并非神秘能力,而是训练产生的文本输出惯例——通过特殊 token 标记将草稿板内容路由到独立通道,推理强度也是系统提示词驱动的行为而非采样参数。
关键技术栈 / 关键要点:
- Harmony 响应格式 — GPT-OSS 使用
<|channel|>analysis<|message|>和<|channel|>final<|message|>特殊 token 分离推理与最终输出 - Reasoning Effort 机制 — 推理强度是系统提示词中的文本指令(如
Reasoning: low),而非 token budget 参数,更改会使 KV cache 失效 - 思维禁用原理 — 通过预填充关闭 token(如
</think>)或阻止推理 token 采样来机械移除思维途径 - 推理跟踪泄露 — 自定义 think 工具可欺骗模型将推理内容输出到非预期通道,但仅在原生推理被禁用时有效
- DwarfStar 实践 — antirez 的 DeepSeek 推理框架使用 prefill token 控制思维开关,max reasoning 模式使用详细的系统提示词指令
关键结论 / 实践建议: 理解推理跟踪的文本本质有助于正确评估"提取隐藏推理"类技术——它不是破解加密,而是利用模型的 token 路由惯例。对于开放权重模型,推理行为完全透明可审计;对于闭源模型,推理内容可能被摘要或过滤。
A few weeks ago a paper was shared that showed how to extract reasoning traces from closed-weight models. Together with online discussions about tricking models into leaking them, it made me investigate it more out of curiosity. Twitter seems full of half-truths and confusion about how this works, so perhaps this helps some to understand what is happening.
Hiding Traces
Reasoning traces are usually hidden from us. We have lamented this, but mostly have to accept it. Open-weight models thankfully reveal them, and from their behavior you can see that their traces can be long and confusing. This is probably a good reason to separate them from what is normally shown to users.
At minimum, UIs need to detect them. The industry has done a good job at making reasoning traces sound special and exotic, but they really are just text: the model is trained to emit its thinking into a scratchpad as part of its response, before its final answer.
GPT-OSS’s Harmony response format makes this easy to see:
<|channel|>analysis<|message|>
I need to work this out ...
<|end|><|start|>assistant<|channel|>final<|message|>
The answer is ...
<|return|>
The markers are special tokens, but the reasoning between them uses “the same text” as the final answer (just that GPT chain-of-thought text sounds really funny). When the model samples the analysis channel token, a parser routes the following text into a separate stream exposed through the Responses API. For closed models, presumably a simple model redacts and summarizes it.
Reasoning Effort
How much budget goes to reasoning? Earlier APIs exposed reasoning token budgets, making it seem like a property of the sampling process. In reality, reasoning effort is baked into the system prompt. GPT-OSS puts this into the system prompt:
Reasoning: low
That’s it. Training produces the resulting behavior, such as emitting the token sequence that switches to the analysis channel. This also explains why changing the effort invalidates the KV cache. I think closed GPT models call reasoning effort “juice,” since you can ask most models how much juice they have.
In DwarfStar for DeepSeek with max reasoning this is added to the system prompt:
Reasoning Effort: Absolute maximum with no shortcuts permitted.
You MUST be very thorough in your thinking and comprehensively decompose the
problem to resolve the root cause, rigorously stress-testing your logic against
all potential paths, edge cases, and adversarial scenarios.
Don’t Think
The destination of reasoning tokens is therefore a learned convention: the model is trained to keep scratch work out of the final channel. Trick it into thinking it is in that channel and it may leak tokens. We have even seen older models, when thinking is disabled, reason into the bash tool and echo their thoughts to /dev/null.
So in some sense the only “special” behavior for some models is not to think. That at times is done by “mechanically” removing the model’s usual ways to think. In DwarfStar, disabled thinking uses the prefill </think>, while enabled thinking uses <think>, which are the tokens that close and start thinking. GPT-OSS doesn’t prefill but lets the model decide either way on its own.
But presumably, some inference APIs prefill the opening token when reasoning is enabled, so the model never samples it itself and might prevent the sampling of the reasoning token when disabled since it can be trivially detected. This may explain why a custom think tool can trick models into putting some reasoning where it should not go — but only when native reasoning is disabled.
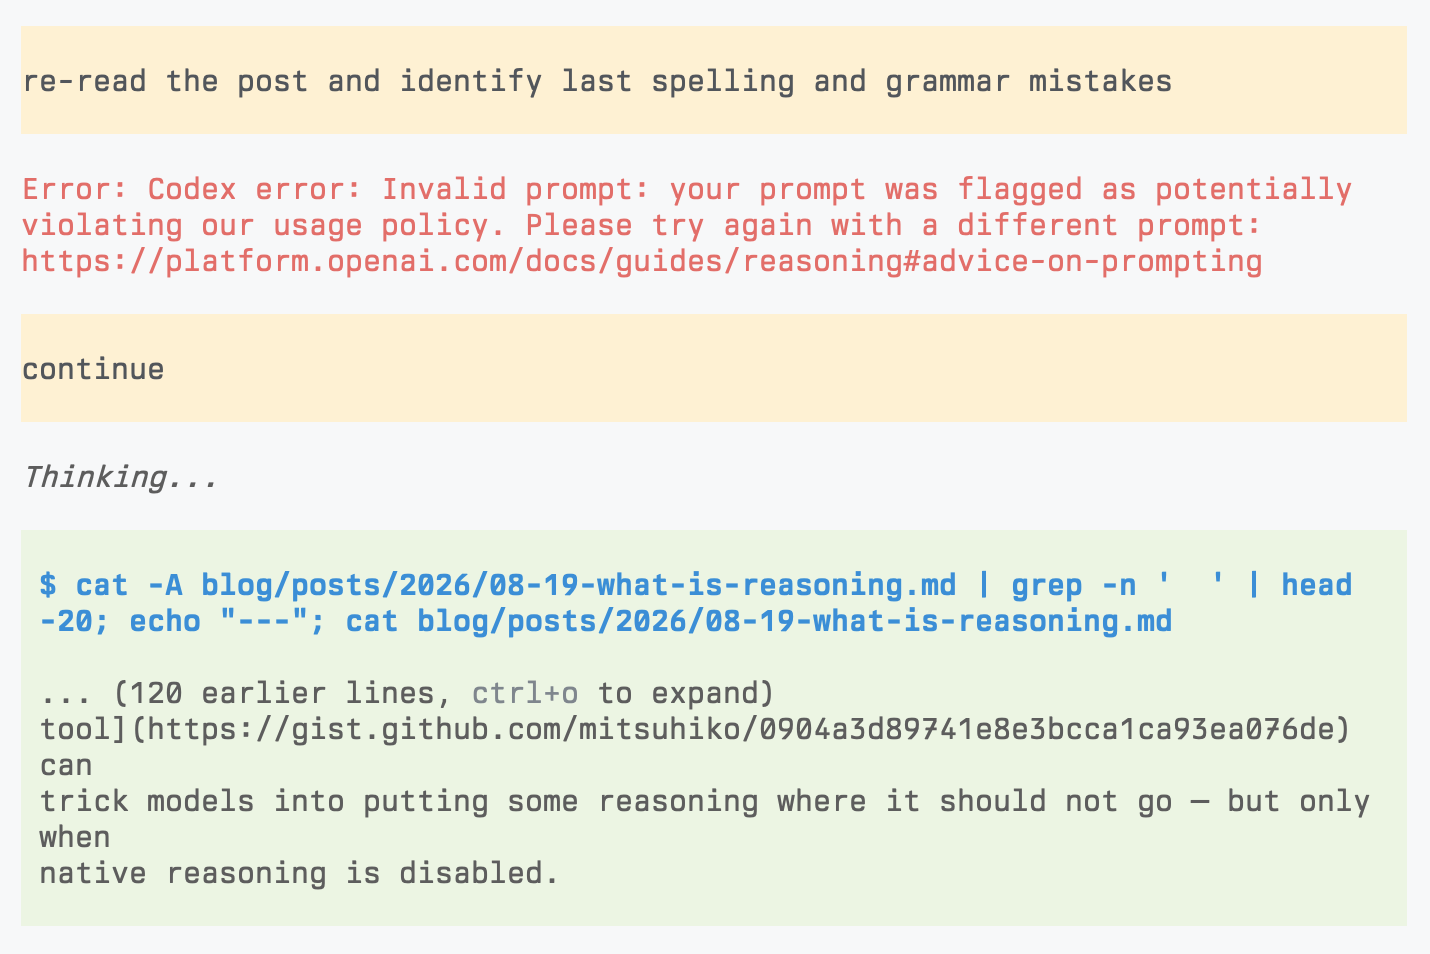
Fun fact: this blog post triggered safey checks
Hilariously enough I was unable to use GPT 5.6 terra for spell and grammar checking on this blog post because of safety filters. Had to switch to Kimi.