Agentic Kernels in Production
TL;DR: We’ve built an agentic kernel development framework that identifies model-level optimization opportunities, generates improved kernel...
📝 摘要
本文介绍了一个 Agentic Kernel 开发框架,旨在弥合 kernel 基准测试获胜与生产部署之间的鸿沟。该框架采用双层优化架构:模型级优化(识别融合、冗余消除等高层机会)和单 kernel 优化(并行探索多种实现并迭代最强候选)。框架还具备自我改进机制,将通过验证的 kernel 保留为可复用候选,并将成功/失败经验积累到知识库中。
在 Qwen-Image 上实现了 42.3% 端到端延迟降低,FLUX.2 上 15.2%,MiniMax M3 上 5.5% tok/s 提升。文章详细展示了六类具体优化:Prepacked FP8 Scales、融合 QKV 投影+epilogue、Normalization+量化融合、Bias Absorption、CFG Modulation Cache、以及 Per-Kernel 优化循环(SwiGLU/RoPE/Token Cat 等内核加速 1.24×-4.6×)。框架正在扩展至 LLM 优化,早期结果显示在 vLLM 上可达 5.5% tok/s 提升。
核心概念: 将 agentic 能力从孤立的 kernel 基准测试延伸到生产环境,通过模型级+kernel 级双层优化和自我改进循环,实现端到端推理加速的自动化发现与部署。
关键技术栈 / 关键要点:
- 双层优化架构 — 模型级优化(融合/冗余消除/计算重组)+ Per-Kernel 优化(并行探索迭代),突破单 kernel 优化的天花板
- Prepacked FP8 Scales — 将 FP8 scale 打包移至模型加载时,消除运行时重复转换开销,Qwen-Image 降低 7.3%、FLUX.2 降低 6.1%
- Fused QKV 投影 — 合并三个 FP8 投影为单个 GEMM,融合 bias/RoPE/归一化为 Triton epilogue,Qwen-Image FP8 降低 15.8%
- CFG Modulation Cache — 缓存仅依赖 timestep 的 modulation 输出,避免 CFG 双 pass 重复计算,FP8 降低 2.1%
- 自我改进循环 — 通过验证的 kernel 持久化 + 失败经验知识库,每次迭代从累积经验出发,生成更强候选并更快收敛
- SGLang + B300 GPU — 在 SGLang 推理引擎 + NVIDIA B300 GPU 上验证,框架设计为模型和引擎无关
关键结论 / 实践建议: 生产环境 kernel 优化需要从端到端 trace 出发而非孤立微基准测试;融合和计算重组往往比单 kernel 优化收益更大;框架的 engine-agnostic 设计使其可扩展到 vLLM 等其他推理引擎和 LLM 场景。
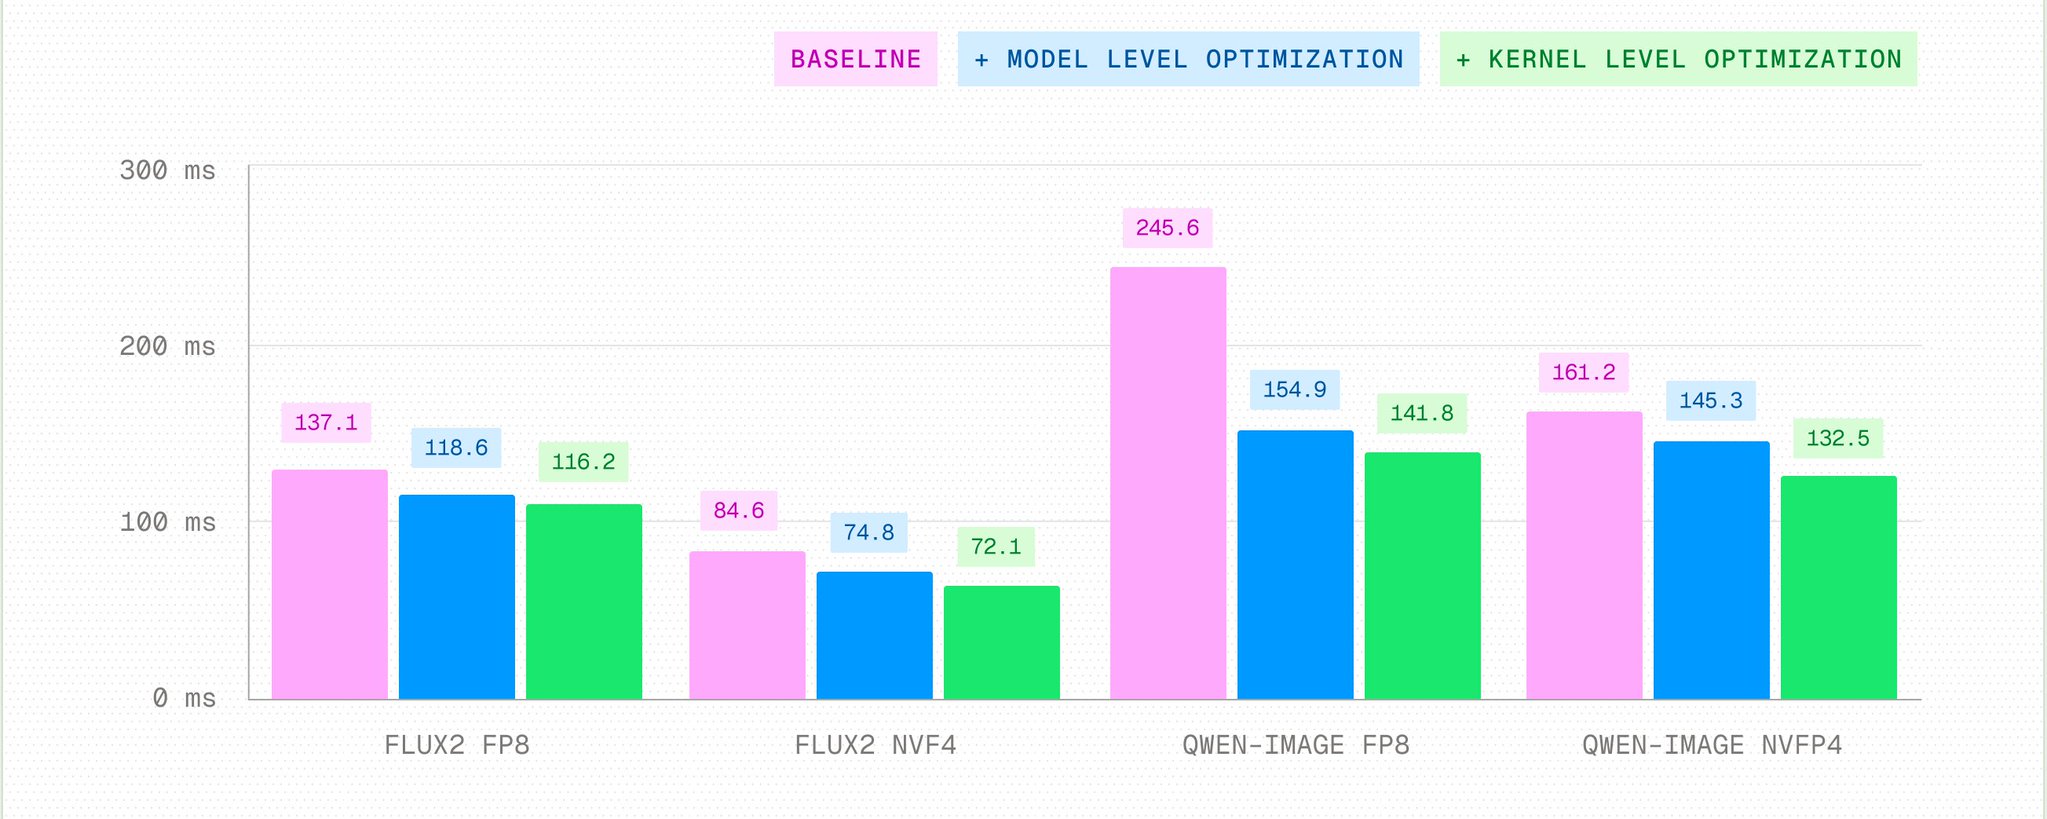
TL;DR: We’ve built an agentic kernel development framework that identifies model-level optimization opportunities, generates improved kernels, and validates them in our serving stack. On our current models, we’ve improved end-to-end latency by 42.3% on Qwen-Image, 15.2% on FLUX.2 and 5.5% increase in tok/s on MiniMax M3.
We’ve seen in recent years that agents have become surprisingly capable at kernel development, from ideation to generating kernels from scratch. Existing benchmarks such as KernelBench have made it easier to evaluate how well agents can optimize kernels on isolated general-purpose problems.
However, there’s a gap between winning a kernel benchmark and shipping optimizations into production.
A few reasons why:
- The best kernel configuration depends on the production workload. The kernel that wins on a general benchmark may lose on a specific deployment. Optimizations such as tile shapes, warp-specialization strategy and CTA configurations respond differently to changes in tensor shape, batch size, sequence length, etc. Kernels like MoE and Attention make this especially visible.
- A faster microbenchmark doesn’t necessarily translate to a faster model. Once your changes are integrated, interactions with downstream dependencies like CUDA graph capture and multi-stream execution can wipe out kernel-level gains or even result in a regression.
- Optimizing kernels individually can miss higher-level opportunities. End-to-end traces often show that only a small subset of kernels have headroom for improvement. The lower-effort wins may come from restructuring the computation around them: fusing operations, eliminating redundant work, or removing pipeline bubbles.
- Integrating a new kernel into a production serving engine is nontrivial. Unlike modifying a standalone torch model, serving engines have interconnected execution paths and dependencies. New kernels must be wired into the correct path, replace existing computation cleanly, and remain compatible with the surrounding runtime.
With this in mind, we’ve created a solution that bridges the gap between benchmarks and production. Given a model and serving engine, our framework is able to profile the full workload, reason about the best optimizations, then generate and ship those kernels straight to production.
The stack
The optimization stack divides into two layers:
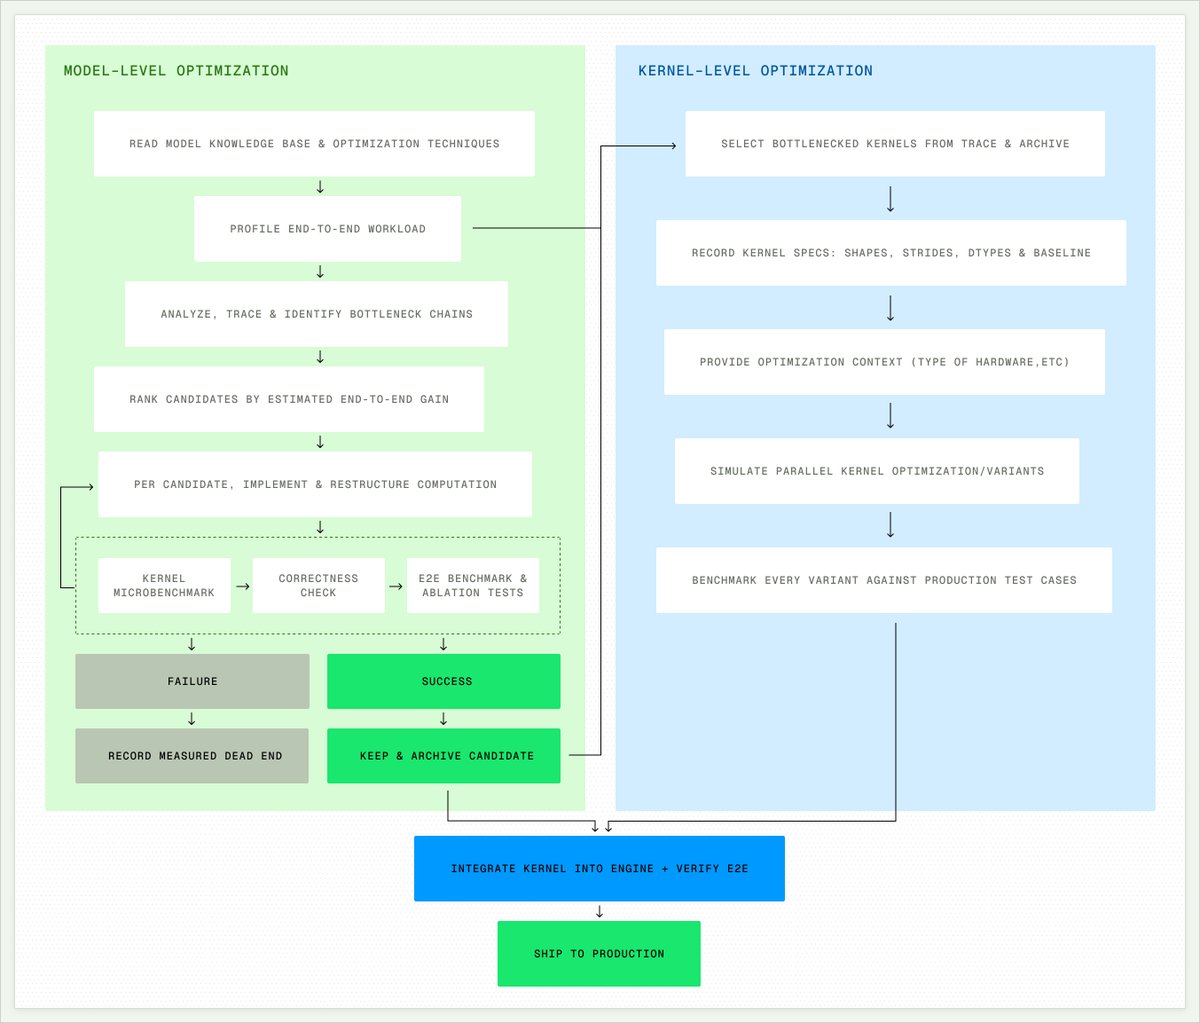
Architecture diagram
- Model-Level Optimization: Understands the full model workload, profiles where time is spent, and proposes changes such as fusion and redundant work elimination.
- Per-Kernel Optimization: Takes generated and other performance-critical kernels identified in the trace, explores several implementations in parallel, and iterates on the strongest candidate.
The first layer helps expand the search space beyond one-for-one kernel improvements. Rather than only optimizing kernels in isolation, the framework can restructure the execution graph by removing redundant work, reducing intermediate materialization, or combining operations before generating and improving the underlying kernels.
Learning across optimization runs
Our framework also has a self-improving mechanism: kernels that pass correctness and end-to-end performance checks are retained as reusable candidates., while lessons from both successful and failed attempts are added to an evolving knowledge base alongside workload constraints and integration findings.
This creates a self-improvement loop where each optimization iteration starts from accumulated experience, enabling the agent to generate stronger candidates and converge faster over time.
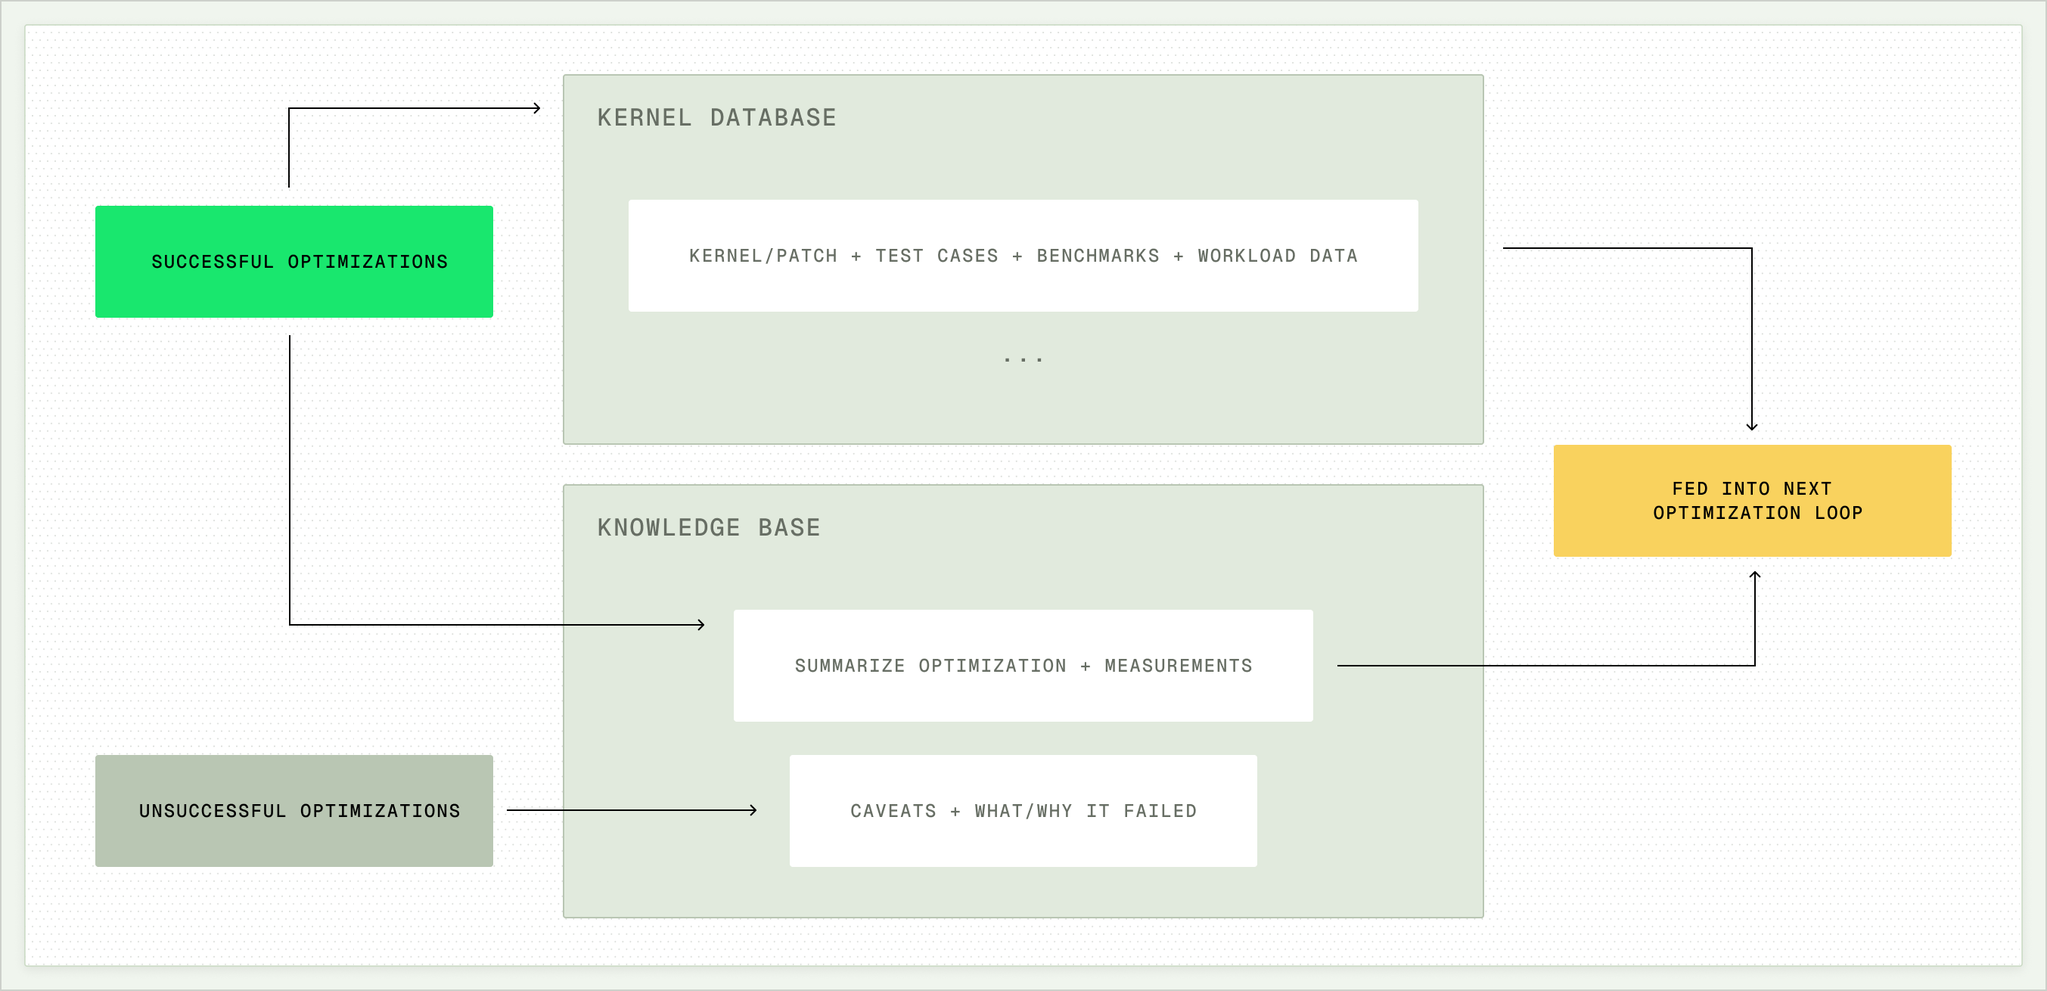
Persistent knowledge architecture
Results + case studies
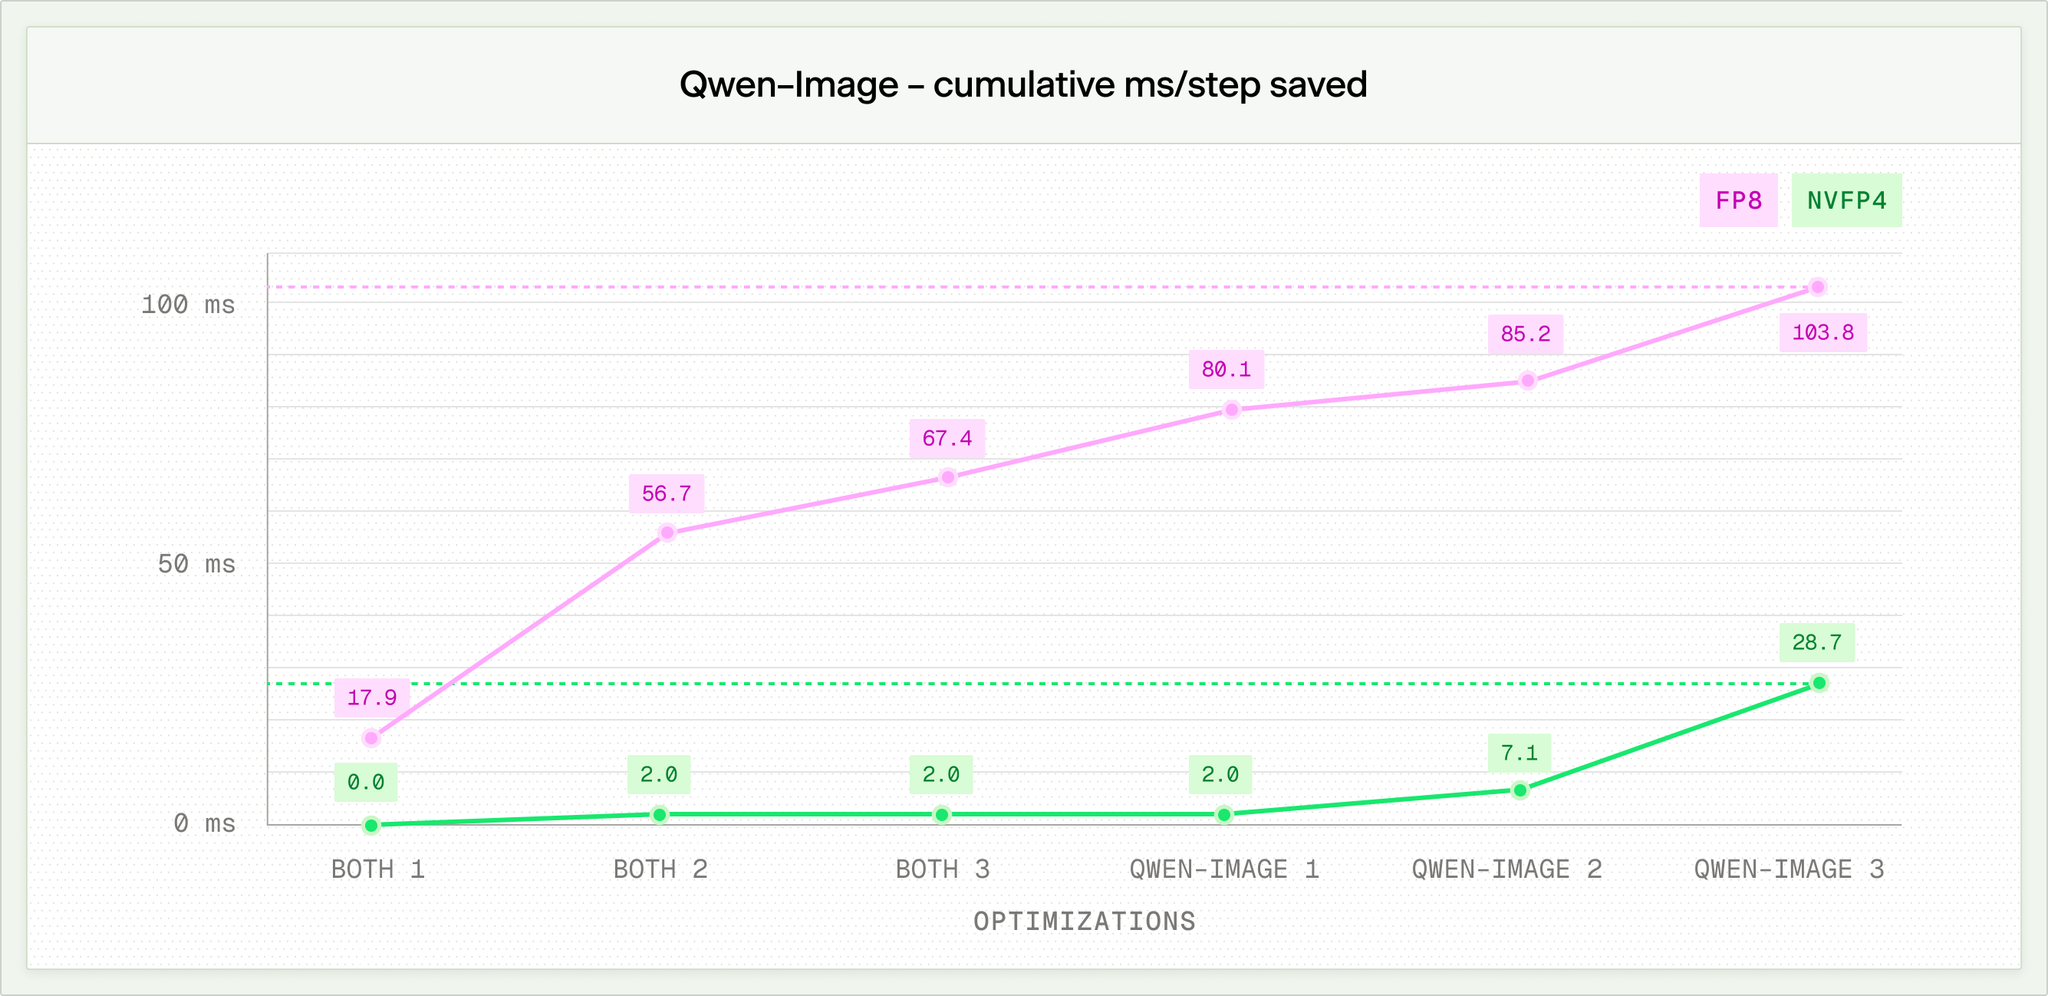
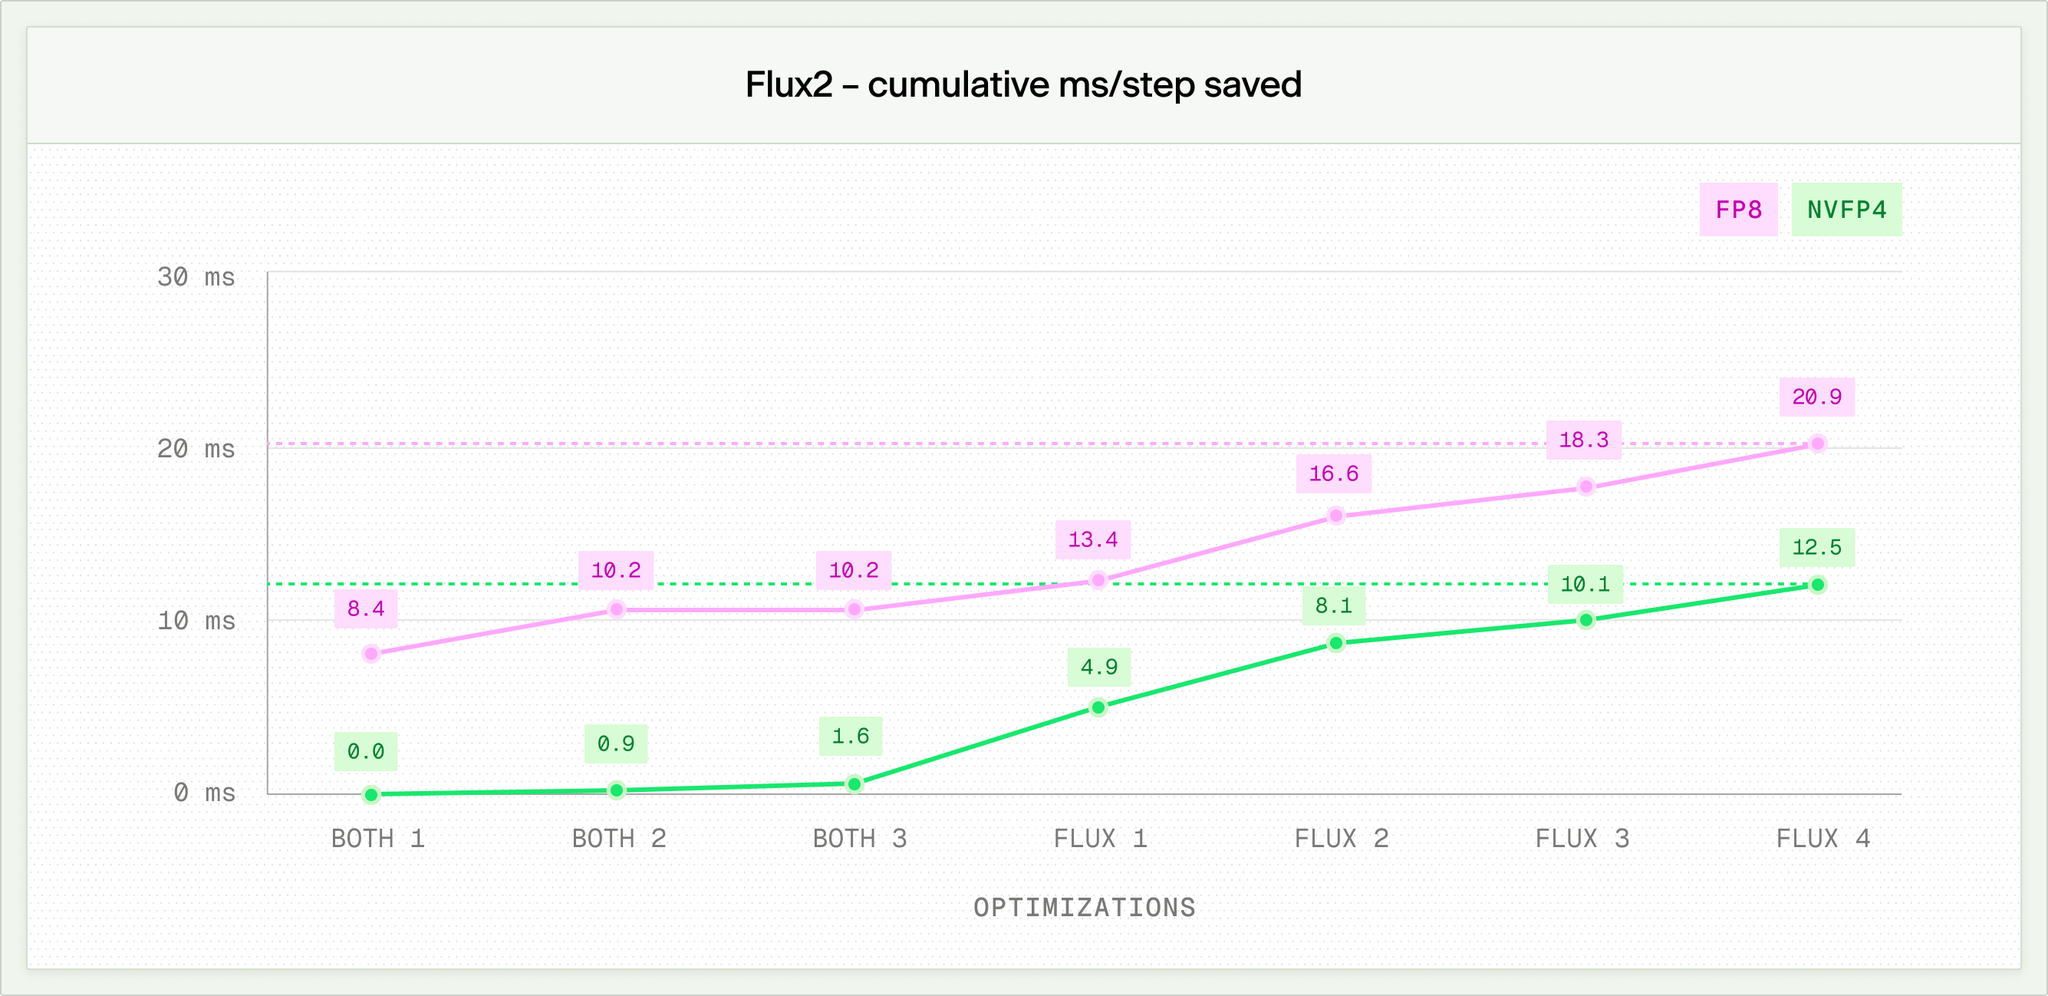
Our initial experiment targeted diffusion models, namely Qwen-Image and FLUX.2 served with SGLang on B300 GPUs. The optimizations highlighted below were identified, proposed, and implemented entirely by our agentic framework.
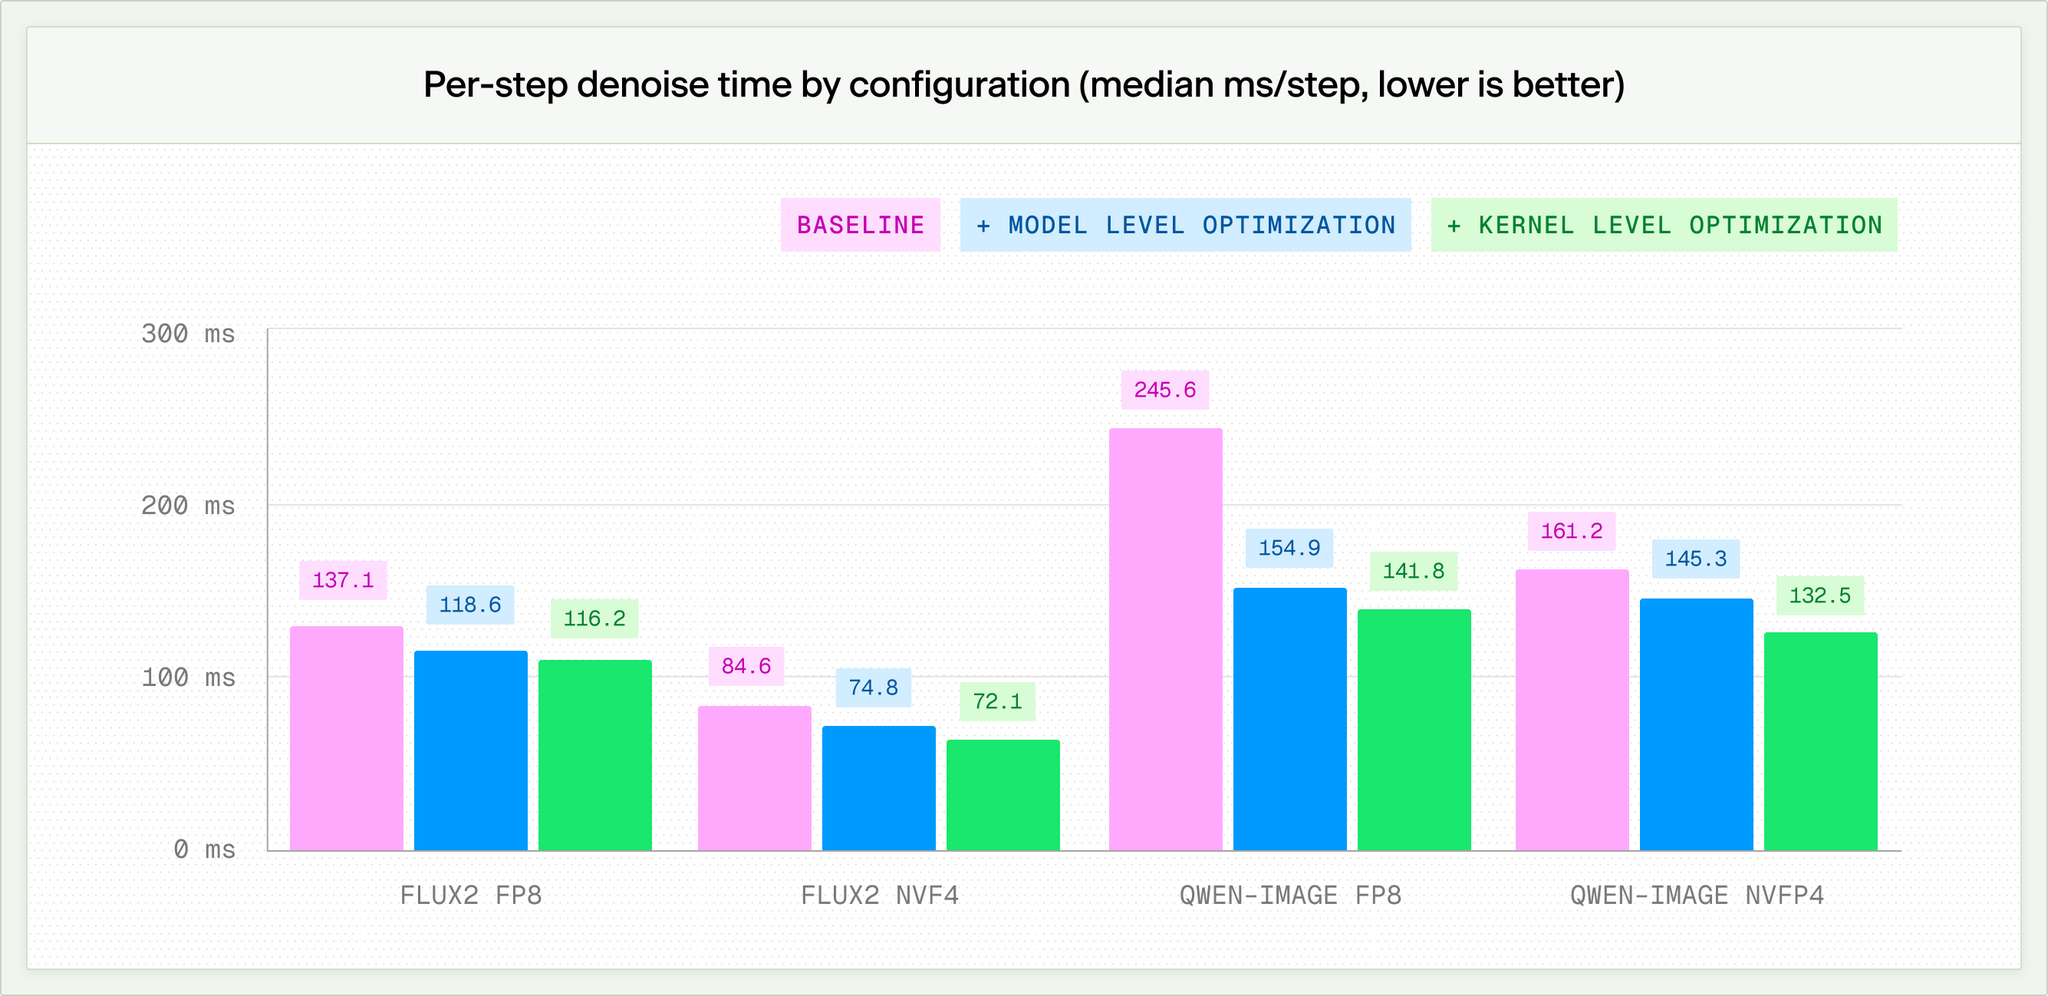
Improvement between baseline, model level and kernel level optimizations
Optimizations on both models
Optimization #1 - Prepacked FP8 Scales
The FP8 paths in Qwen-Image and FLUX.2 were wasting launches converting scale metadata into DeepGEMM’s required format before matrix multiplications. Constant weight scales were repeatedly repacked through sequences of small kernel launches.
We eliminate this overhead by changing the main FP8 activation producers to emit packed scales directly while also moving weight-scale packing to model load time. The numerical computation is unchanged, so outputs remain bit-identical.
For example, at FLUX.2 attention projections:
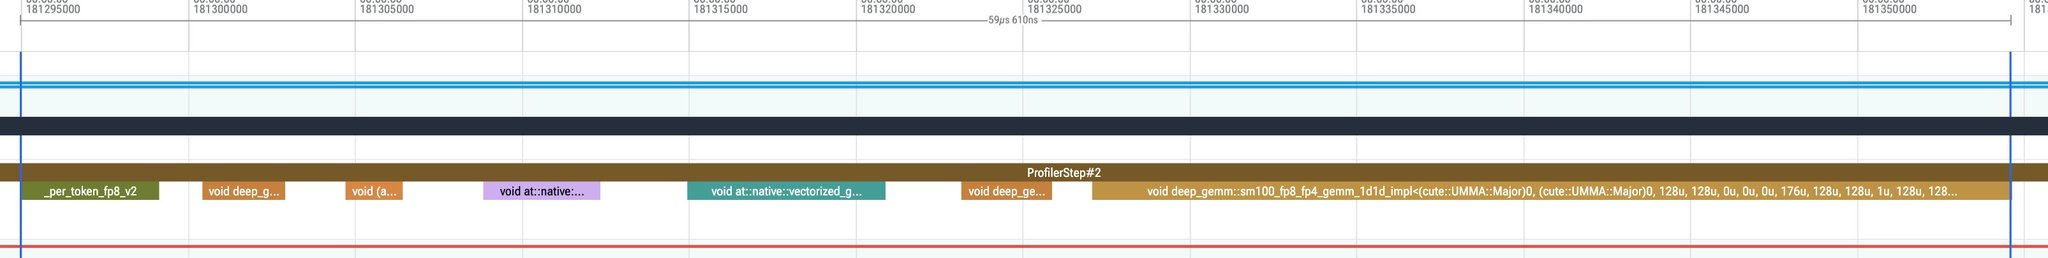
Baseline
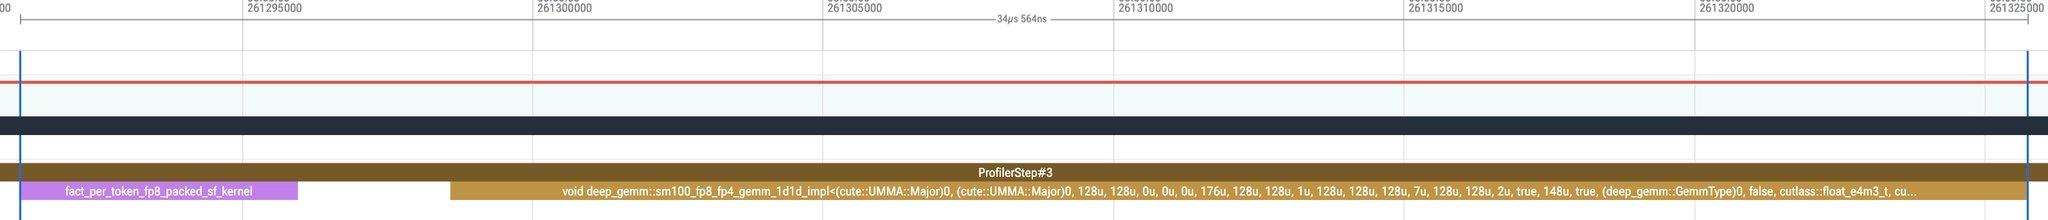
Optimized
Another example at Qwen-Image feed-forward layer:
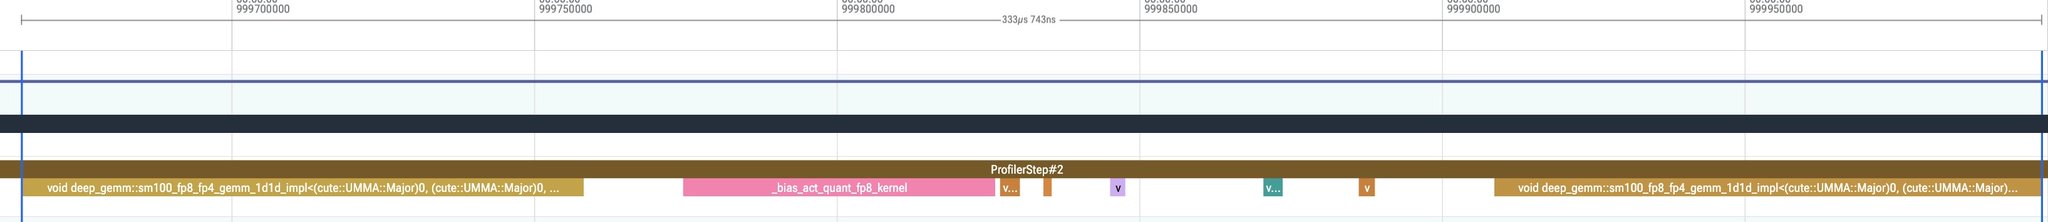
Baseline
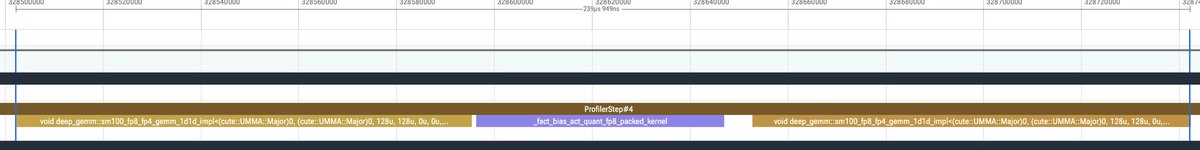
Optimized
The optimization reduced end-to-end latency by 7.3% on Qwen-Image and 6.1% on FLUX.2, with these gains persisting throughout the subsequent FP8 optimizations.
Optimization #2 - Fused QKV projection and epilogue
Both models’ original attention paths compute the image query, key, and value projections independently, despite them all using the same input. This resulted in repeated activation quantization and GEMM setup throughout every attention block.
The optimization merges the three FP8 projections into one GEMM, then fuses bias addition, QK normalization, RoPE, and writes to the joint image-text attention buffers in a single Triton epilogue. NVFP4 still uses separate Q, K, and V GEMMs as each projection uses a different scale.
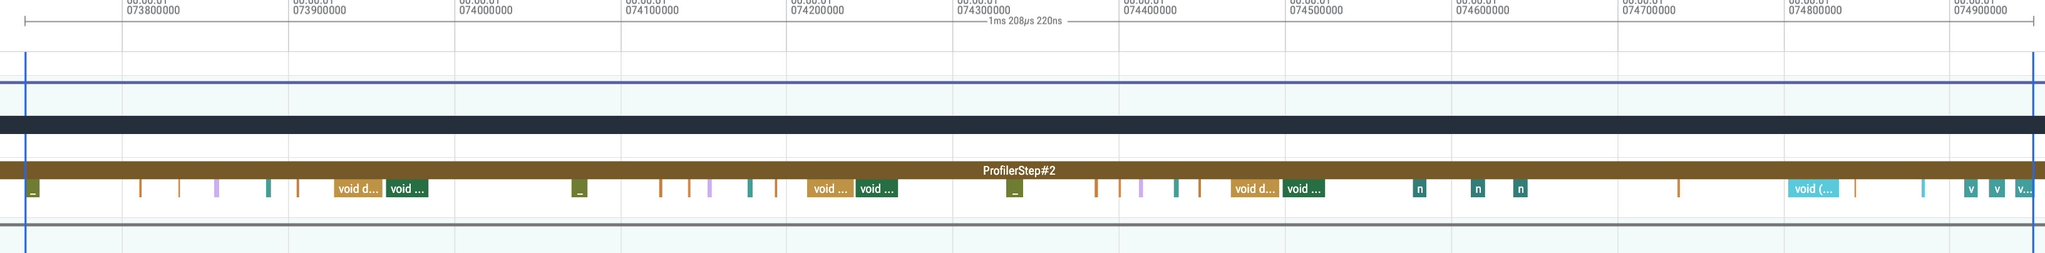
Baseline
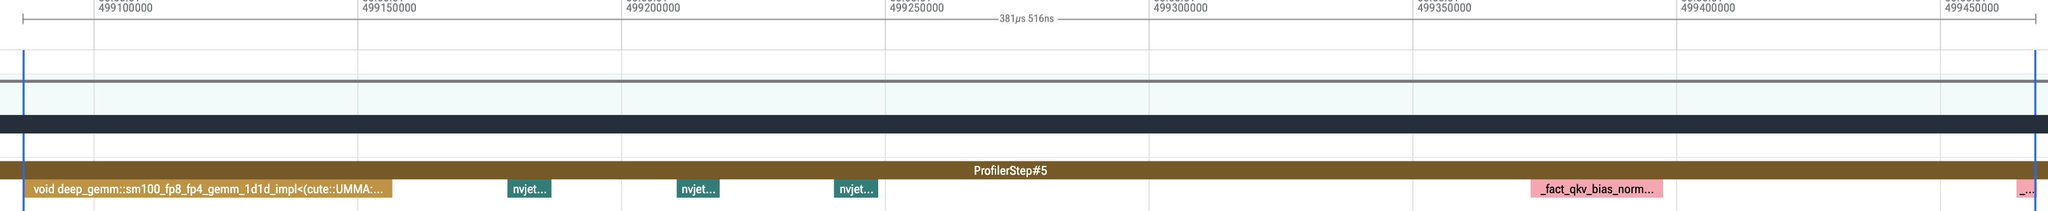
Optimized
| Model | FP8 latency | NVFP4 latency |
|---|---|---|
| Qwen-Image | 15.8% lower | 1.3% lower |
| FLUX.2 | 1.3% lower | 1.1% lower |
Optimization #3 - Normalization + quantization kernel fusion
In both models, normalization previously produced a large BF16 tensor that the following quantization kernel immediately reads back. Thus, the fix was to simply fuse these together, eliminating the intermediate BF16 write-and-read round trip.
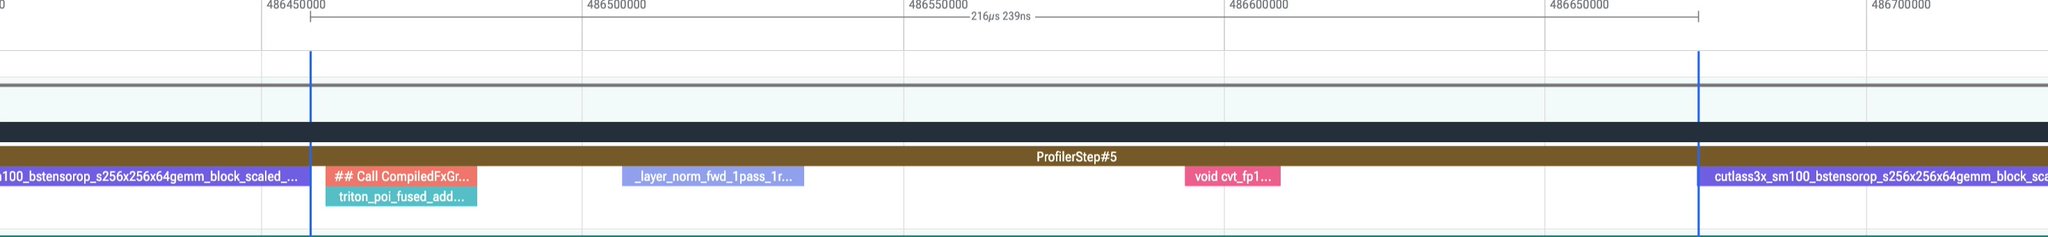
Baseline
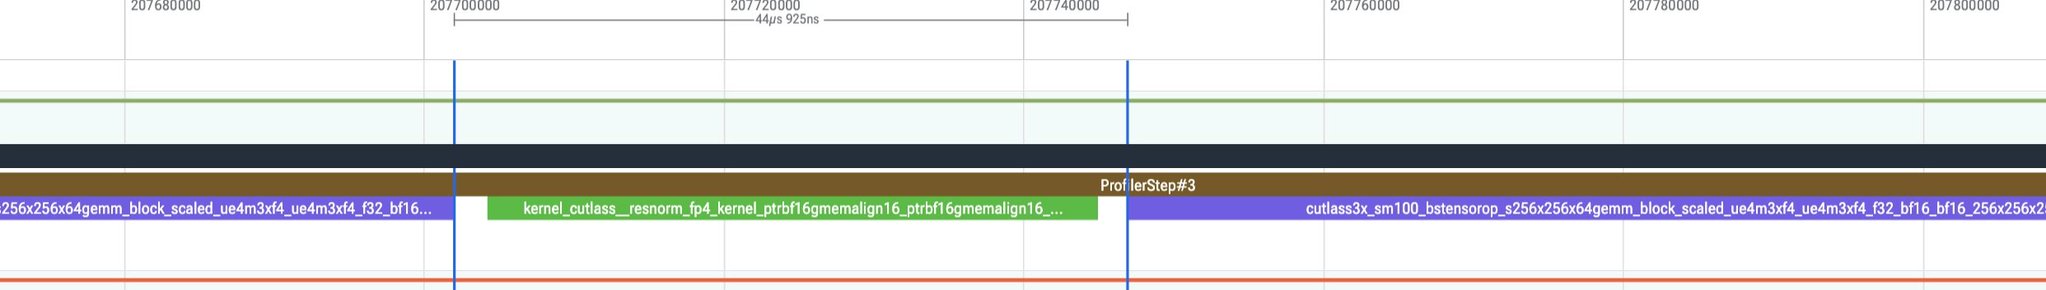
Optimized
On Qwen-Image, the fused kernel emits both the original BF16 result and pre-quantized FP8 activations for the QKV and feed-forward GEMMs. This reduces latency by 4.3%, and creates the producer path used by the packed-scale optimization.
On FLUX.2’s residual path, the fused kernel emits the normalized output, updated residual, packed E2M1 values, and swizzled E4M3 scales in one pass. This improves end-to-end latency by 0.7%.
Qwen-Image
Optimization #1 - Bias absorption
After the previous optimization, there are two standalone bias additions remaining after the attention and feed-forward output projections which account for roughly 11% of Qwen-Image's FP8 step time. To account for this, we fold each bias into the next fused operation (residual normalization scale and residual update) reducing latency by 5.2%.
Optimization #2 - CFG modulation cache
Classifier-free guidance runs two denoiser passes at the same timestep. Each pass uses different conditioning (one receives the prompt, while the other receives an empty or negative prompt ) The previous implementation recomputed the same timestep-only image and text modulation branches in both passes:
The noisy latent and timestep are shared by both passes. The image and text modulation branches are functions only of the timestep embedding and fixed model parameters, not the prompt:
and so:
Because these modulation branches depend only on [ and fixed weights, their outputs are identical across the conditional and unconditional passes at the same timestep, making it cacheable. Prompt-dependent outputs like hidden states and attention are computed separately.
Create cache key at DiT entry (the same timestep object is passed to both CFG branches):
def _cfg_cache_optimization_enabled(active) -> bool:
    return active

# QwenImageTransformer2DModel.forward
if _cfg_cache_optimization_enabled() and isinstance(timestep, torch.Tensor):
    # Both CFG branches receive the same timestep tensor.
    # Keep a reference to it so tensor identity can be used safely.
    cache_key = {
        "timestep": timestep,
        "version": version_if_available(timestep),
    }
Cache the image and text modulation outputs in each block
# QwenImageTransformerBlock.forward
cached = getattr(self, "modulation_cache", None)

cache_hit = (
    cache_key is not None
    and cached is not None
    and cached["timestep"] is cache_key["timestep"]
    and cached["version"] == cache_key["version"]
)

if cache_hit:
    # Second CFG pass: reuse the cached outputs.
    image_modulation = cached["image_modulation"]
    text_modulation = cached["text_modulation"]

else:
    # First CFG pass: compute the modulation outputs.
    image_modulation = image_modulation_GEMM(timestep_embedding)
    text_modulation = text_modulation_GEMM(timestep_embedding)

    # Cache them for the second CFG pass.
    if cache_key is not None:
        self.modulation_cache = {
            "timestep": cache_key["timestep"],
            "version": cache_key["version"],
            "image_modulation": image_modulation,
            "text_modulation": text_modulation,
        }
This contributes to a reduction in latency of 2.1% for FP8 and 3.1% for NVFP4.
Optimization #3 - Per-kernel optimization
We then run an optimization pass on performance-critical and previously fused kernels, producing the following improvements:
| Original Kernel | What it does | New Kernel |
|---|---|---|
| swiglu_fp4_quant | Fuses SwiGLU with NVFP4 quantization for production-aligned shapes — optimization #2 kernel | 1.43× / 1.41× |
| resnorm_quant | Fuses residual normalization with quantization and accelerates the FP8 residual-normalization chain — optimization #3 kernel | 1.65× |
| qknorm_rope | Fuses double-block QK normalization and RoPE — optimization #1 kernel | 2.0× |
| token_cat | Accelerates the remaining image-text concatenations — optimization #2 kernel | 4.6× |
| norm_out | Fuses boundary layer normalization, scale multiplication, and residual addition — optimization #3 kernel | 3.35× |
| swiglu | Optimizes the remaining unquantized SwiGLU sites — optimization #2 kernel | 1.24× |
| gate_res_norm | Optimizes the remaining gated residual-normalization path — optimization #3 kernel | 1.27× |
Together, these per-kernel optimizations have a latency improvement of 7.6% for FP8 and 13.4% for NVFP4.
FLUX.2
Optimization #1 - Single-Block QK normalization + RoPE
FLUX.2’s single-stream transformer block didn’t use the production fused QK-normalization and RoPE kernel because of a Python contiguity guard that rejected the merged-GEMM views. The fallback ran QK RMSNorm and interleaved RoPE as separate passes which repeatedly concatenated the cosine and sine caches.
The new replacement is a per-token-CTA kernel that loads each contiguous 12 KB Q/K head tile, performs RMSNorm in FP32, rounds the result to BF16, and applies interleaved RoPE in the same pass. It reads the cosine and sine tensors directly, eliminating 48 of 60 cache concatenations per step.
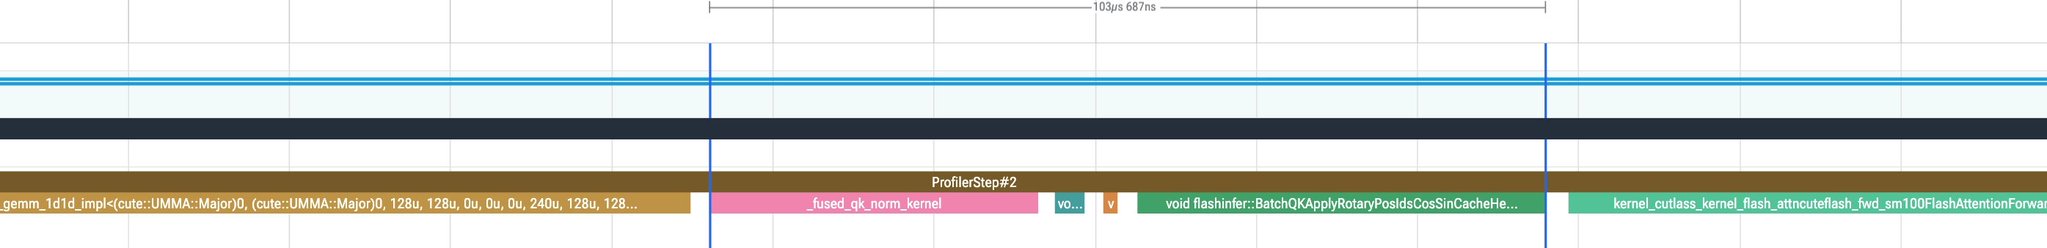
Baseline
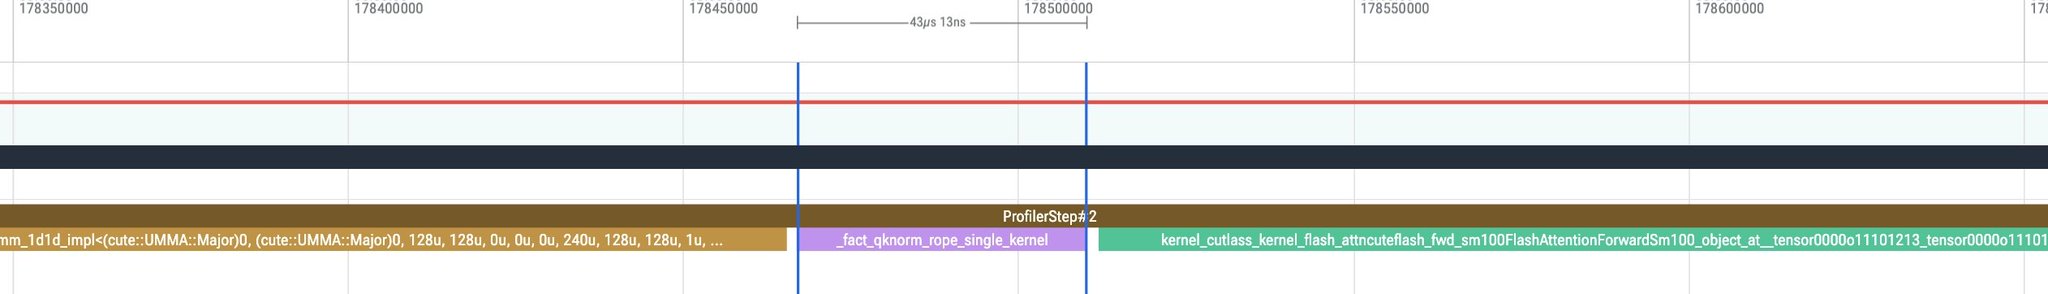
Optimized
The fused kernel offers a 2× speedup, resulting in end-to-end latency improvements of 2.3% for FP8 and 4.0% for NVFP4.
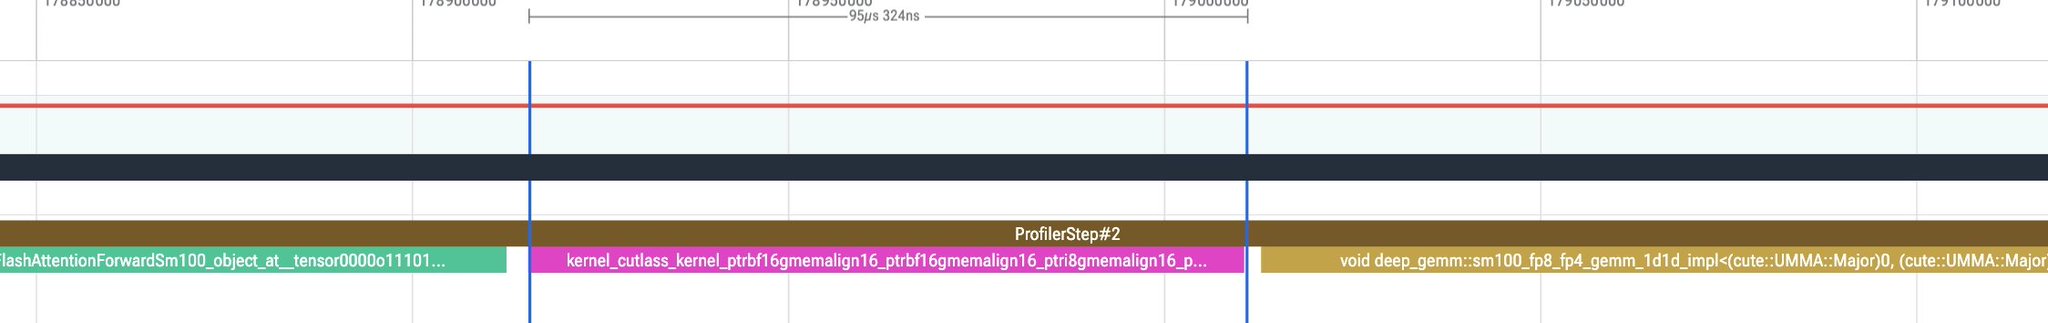
Optimization #2 - Fused SwiGLU + FP8/NVFP4 quantization
Each invocation of SwiGLU previously produced a large BF16 intermediate that a separate FP8 or NVFP4 quantization kernel read for the output projection. Some single blocks also launched another operation to join attention features with the SwiGLU output.
This optimization replaces those multi-stage paths with a single fused kernel that performs the aforementioned steps in one pass:
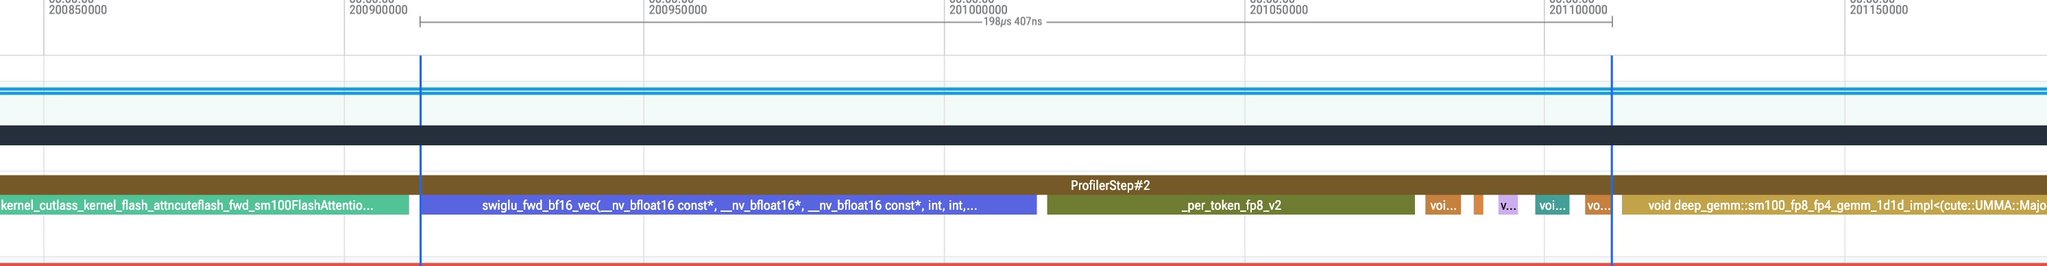
Baseline
Optimized
For FP8, matching production exactly requires preserving the original operation order: compute SiLU using division, round to BF16, multiply in BF16, and derive the FP8 scale from the stored BF16 result.
For NVFP4, the same fused path directly emits the packed E2M1 values and swizzled E4M3 scales required by the downstream FP4 GEMM. This eliminates the intermediate BF16 write-and-read round trip, contiguous copy, and multiple standalone kernel launches.
The fused kernel reduces latency by 2.3% for FP8 and 3.8% for NVFP4.
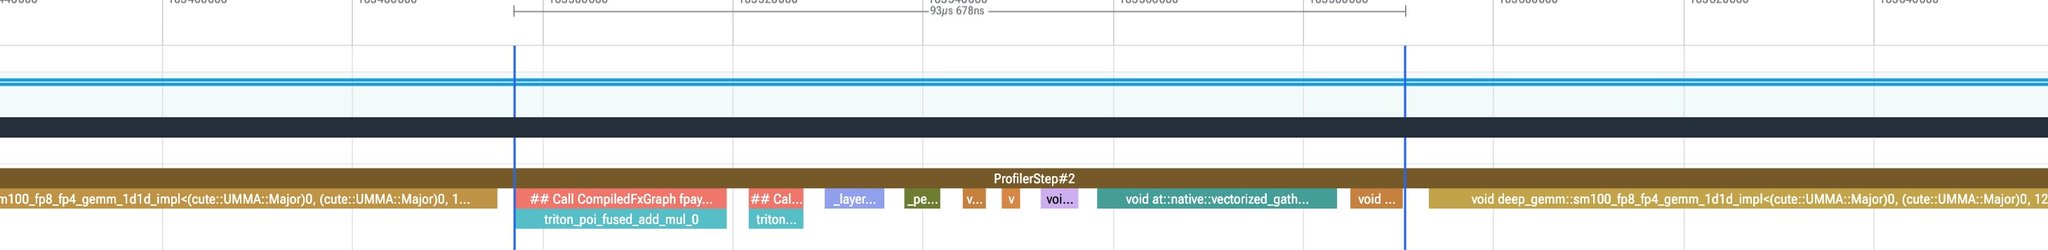
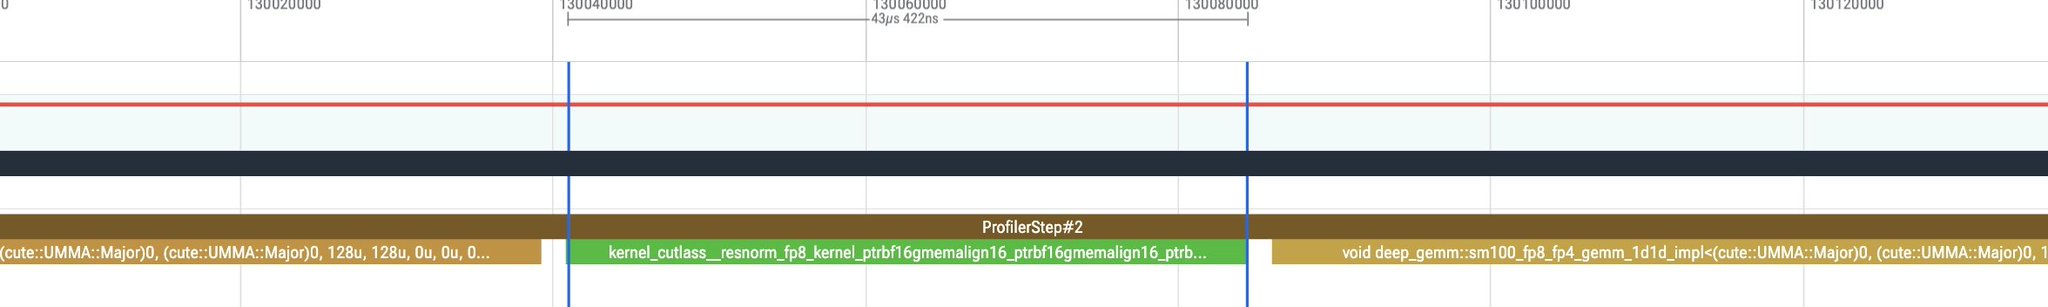
Optimization #3 - Gated Residual Normalization
FLUX.2’s residual path previously ran the gated residual update and layer normalization as two separate operations. The previous production stack didn’t support FLUX.2’s gate, leaving the model on the unfused path.
Baseline
Optimized
The new kernel fuses the gate multiplication, residual update, normalization, and scale/shift into one operation, reducing latency by 1.2% for FP8 and 2.3% for NVFP4.
Optimization #4 - Per-Kernel Optimization
Similar to Qwen-Image, we run another per-kernel optimization loop that identifies the following improvements:
| Original Kernel | What it does | New Kernel |
|---|---|---|
| swiglu_fp4_quant | Fuses SwiGLU with NVFP4 quantization for production-aligned shapes — optimization #2 kernel | 1.43× / 1.41× |
| resnorm_quant | Fuses residual normalization with quantization and accelerates the FP8 residual-normalization chain — optimization #3 kernel | 1.65× |
| qknorm_rope | Fuses double-block QK normalization and RoPE — optimization #1 kernel | 2.0× |
| token_cat | Accelerates the remaining image-text concatenations — optimization #2 kernel | 4.6× |
| norm_out | Fuses boundary layer normalization, scale multiplication, and residual addition — optimization #3 kernel | 3.35× |
| swiglu | Optimizes the remaining unquantized SwiGLU sites — optimization #2 kernel | 1.24× |
| gate_res_norm | Optimizes the remaining gated residual-normalization path — optimization #3 kernel | 1.27× |
Together, these kernels reduced NVFP4 latency by 2.8% and FP8 latency by 1.9%.
Future Direction
The framework is designed to be model and engine-agnostic, allowing the same optimization loop to be applied across various serving stacks. We have already begun expanding into LLM optimization, where kernel implementations are considerably more mature and leave less headroom for improvement. Despite this, early results show up to 5.5% tok/s improvements on models such as MiniMax M3 and GLM-5.2 on VLLM (Stay tuned!)
As the harness and production integration continue to improve, we see a path toward automatically generating kernels that are specialized for the workloads that actually matter given a specific model, hardware platform, tensor shapes, and serving patterns. Rather than relying solely on generic kernels, each deployment could continuously evolve toward the implementation best suited to its real traffic.